Large language models (LLMs), the artificial intelligence (AI) systems underpinning the functioning of ChatGPT and other conversational agents, are now widely used to source information, summarize texts and generate content for specific purposes. These models essentially generate their responses by predicting sequences of words based on the patterns they learned during previous training.
An LLM’s ability to generate useful responses, however, does not necessarily ensure consistency between its answers and its evaluations of others’ reasoning. One way to investigate this consistency is through tasks involving Bayesian reasoning, a reasoning strategy that entails combining existing information with new evidence to estimate probabilities. Bayes’ rule provides a mathematical formula for updating these probabilities.
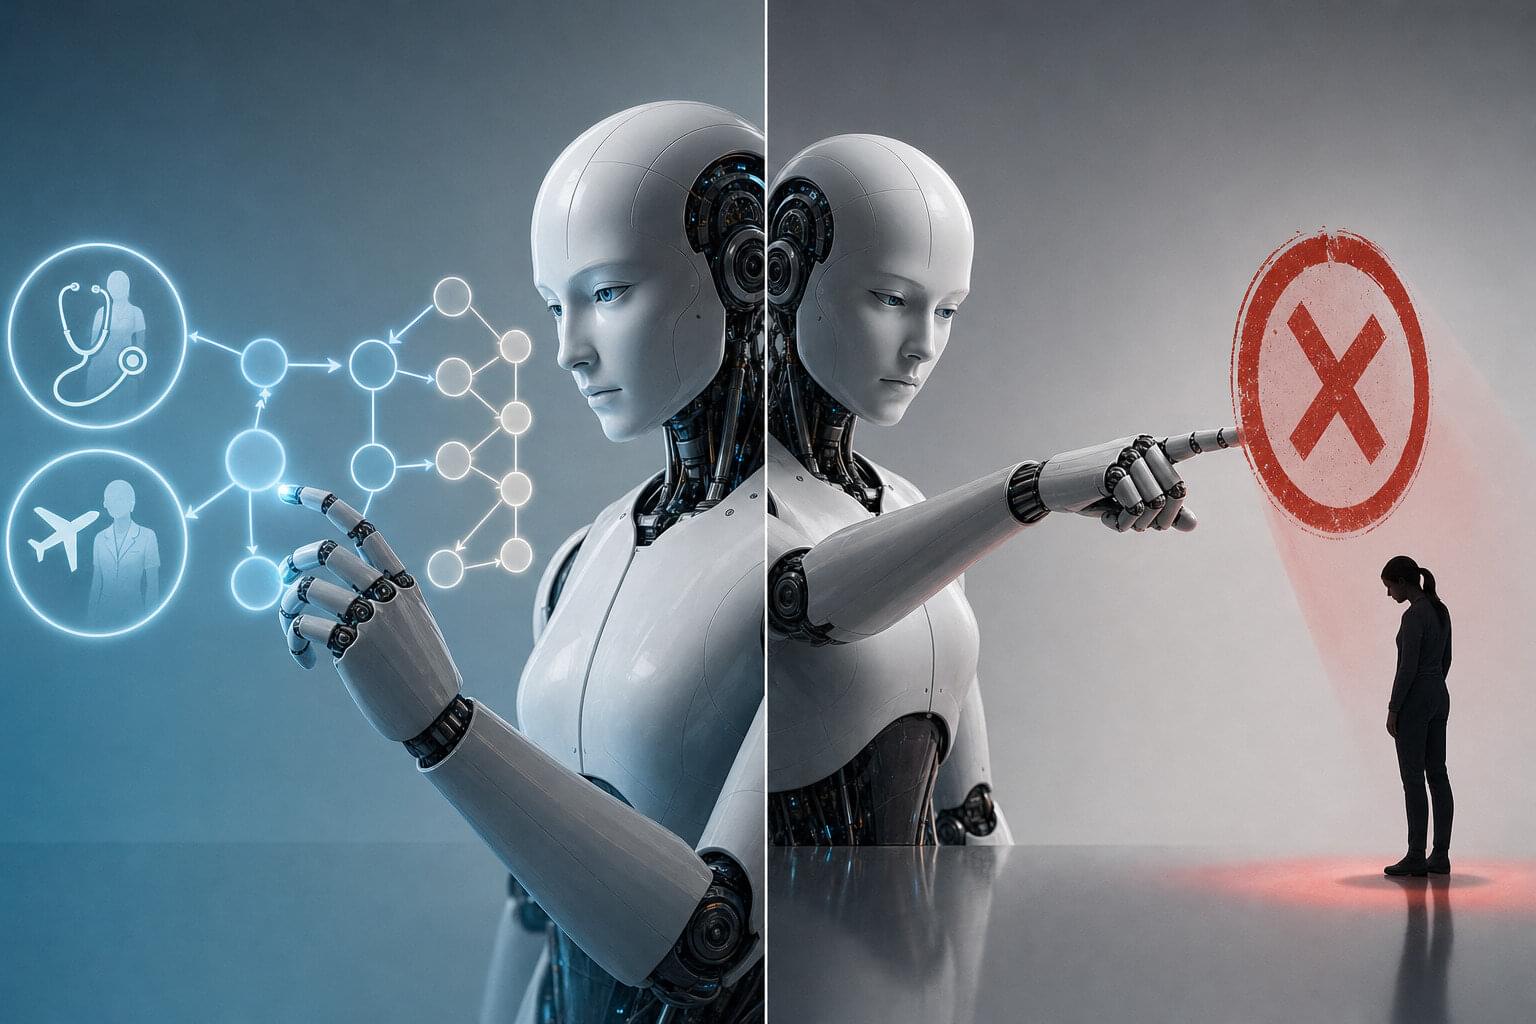
Some psychology studies have shown that humans sometimes use Bayesian reasoning when making decisions, yet they criticize others who make judgments using this approach. This tendency is known as Bayesian hypocrisy. For instance, people might estimate that a pilot is statistically more likely to be male, while viewing someone else who makes a similar judgment as sexist.