Ellisen, CPZN 4,204,185 Cambridge Street, Boston, Massachusetts, 2,114, USA. Email: [email protected].
Find articles by Guo, C. in: | Google Scholar | 
1Mass General Brigham Cancer Institute, Boston, Massachusetts, USA.
Ellisen, CPZN 4,204,185 Cambridge Street, Boston, Massachusetts, 2,114, USA. Email: [email protected].
Find articles by Guo, C. in: | Google Scholar |
1Mass General Brigham Cancer Institute, Boston, Massachusetts, USA.
Most arguments about AI still begin with autonomy: how much should these systems be allowed to do on their own? It is a fair question, but it is not the one that decides whether an institution can use them.
A very capable system can be governed if people can read its rules, cap its authority, rerun a decision and see what an update changed. A modest chatbot can be impossible to govern if its behavior is spread across model weights, training data, prompts, retrieval, filters, tools, vendor policy and decisions no one recorded.
The industry has become good at controlling what a system says. It has not found a way to control the moment its behavior changes. When a vendor ships an update, most deployed systems give the customer no single place to see what changed, which rule produced a given result, or whether the limit the customer signed off on still holds. That gap matters more each month, as these systems move from answering questions to acting inside companies, hospitals and infrastructure.
How can an AI memory learn the patterns behind the patterns?
A new study, Hierarchical Prototype Emergence in Modern Hopfield Models, explores how associative-memory models can learn not just individual examples, but the deeper structure connecting them—and potentially use that structure to create new, sensible examples. https://arxiv.org/abs/2609.
The researchers study a modern version of a Hopfield network, an AI system designed to store and retrieve patterns. Instead of treating every memory as unrelated, they organize the memories into a hierarchy, much like a family tree: individual images belong to groups, groups share broader characteristics, and those groups may themselves belong to larger categories.
The key question is whether the network can go beyond simply remembering the images it was given. The researchers find that, under certain conditions, the network develops prototypes—stable representations that capture common features shared by multiple memories. In other words, rather than memorizing a particular example, the system can discover something like the “essence” of a group and reconstruct a new example from it.
Interestingly, the amount of information needed to achieve this kind of generalization grows only quasi-polynomially with the complexity of the hierarchy, suggesting that learning these higher-level patterns may be considerably more efficient than simply memorizing every possible combination.
The researchers also find similar behavior when testing Fashion-MNIST data: the transition between memorization and prototype formation depends on factors such as how many memories the network stores and the sharpness of its activation function.
The broader significance is that this provides a mathematical “toy model” for a much bigger question in AI: how can a system move from memorizing examples to learning hierarchical structure and generating something genuinely new from that structure? Understanding this process in Hopfield models could offer clues about more sophisticated generative architectures, including diffusion models.
This is especially interesting because it frames generalization as the emergence of stable higher-level representations, rather than simply as better recall of training examples.
A new benchmark from Dalian University of Technology (VA-Bench) tested 12 multimodal AI models on robot-arm manipulation tasks.
The results are consistent and uncomfortable: • Object location accuracy: ~100% • Task understanding: ~99% • Whole-task success (best model): only 53.93%
The more important gap is between detecting an error (73.6%) and correcting it in real time (46.7%). Dual-arm tasks collapsed further — single-arm success around 65%, dual-arm only 11%.
Simulation is teaching models what to see and what needs to be done. It is still failing to teach them how to reliably complete the action when conditions change.
For buyers evaluating robotics vendors: treat simulation demo success rates as an upper bound, not a production prediction. Ask for dual-arm success rates on held-out tasks, error-correction rates, and performance when object geometry varies before approving any pilot.
Full analysis:
#Robotics #Simulation #IndustrialAI #Procurement
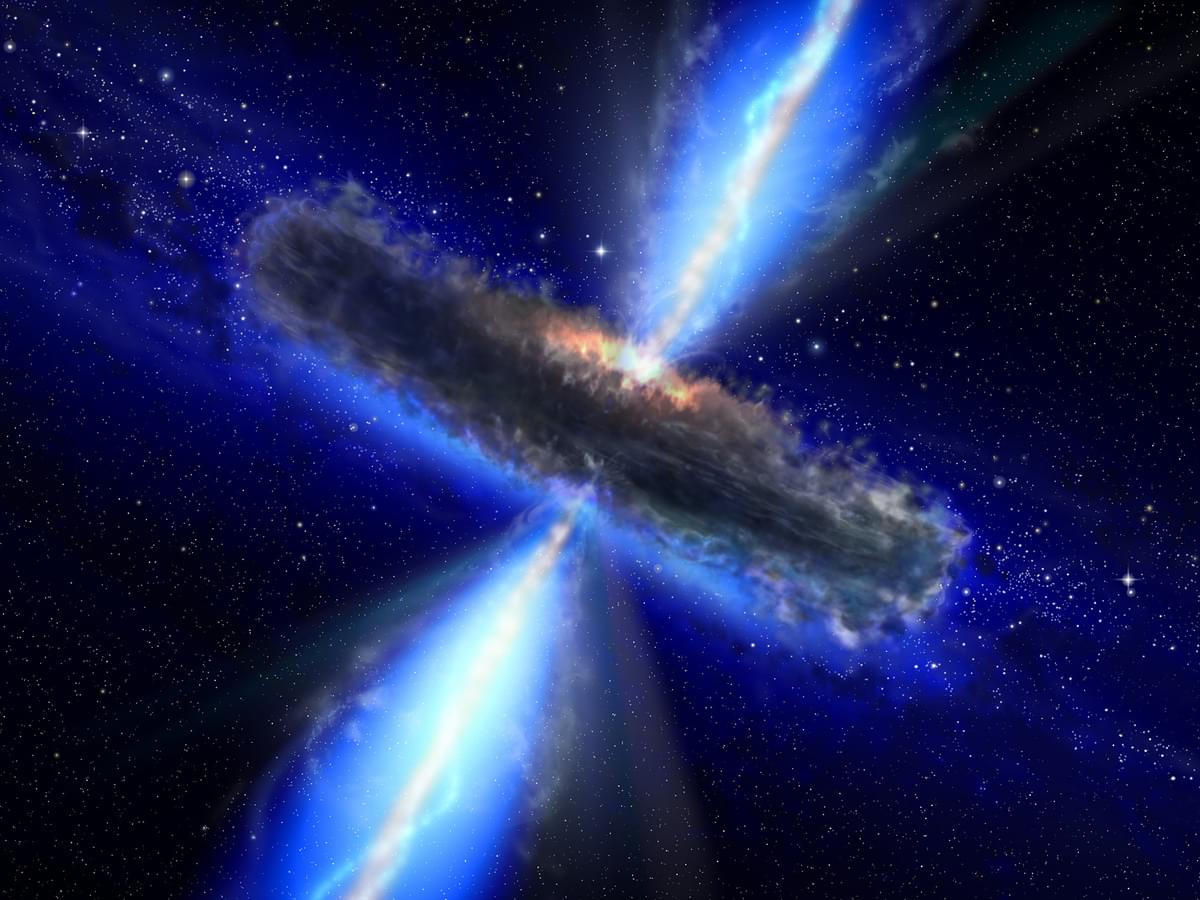
JWST reveals that newborn planets are racing against powerful winds and radiation before their supply of planet-building gas disappears. JWST has revealed that young planetary systems lose their planet-building gas through a changing mix of powerful jets, molecular winds, and radiation-driven outflows. As the disks age and their gas disappears, giant planets face a shrinking window to build massive atmospheres.
Planets take shape inside disks of gas and dust surrounding young stars, but the supply of gas they depend on is temporary. New observations from NASA’s James Webb Space Telescope (JWST) are giving astronomers a clearer picture of how that gas escapes and how the dominant escape mechanisms change as planetary systems mature.
The study, led by Naman Bajaj of the University of Arizona and coauthored by SETI Institute scientist Uma Gorti, examined 72 young, Sun-like stars and their protoplanetary disks. It is among the largest studies of planet formation conducted with JWST and suggests that different kinds of winds dominate at different stages of a system’s early development.
Science has increasingly used artificial intelligence (AI) as a kind of microscope—sorting data, analyzing images and revealing hidden patterns. Now a new shift is underway: AI that not only breaks down data but also helps scientists decide what to do next through simple, natural language requests.
With this emerging technology—agentic AI—scientists can ask questions and direct actions in everyday language. The system then helps perform or determine next steps, turning complex workflows into straightforward, chat-powered conversational exchanges.
At the U.S. Department of Energy’s (DOE) Argonne National Laboratory, researchers recently demonstrated this agentic AI capability as part of the Synergistic Neutron and Photon Science—Intelligence (SYNAPS-I) project, which integrates data from neutron, X-ray and microscopy experiments across national labs into a single effort.
HELIOX: WHERE EVIDENCE MEETS EMPATHY 🇨🇦
The laptop that broke the rules.
https://youtu.be/Ni0sNC9sabc](https://youtu.be/Ni0sNC9sabc)
A laptop with 4GB of video memory just fine-tuned an 8-billion-parameter AI model — something conventional machine learning wisdom says is flatly impossible.
In this episode, we trace independent researcher Alpamys Makazhan’s journey through “Exact Layer Streaming,” a technique that outran an enterprise H100 data center GPU, exposed a silent memory-corruption bug buried in a library the entire AI industry relies on, and forced its own author to publicly retract his own explanation when the data proved him wrong.
We dig into the silent failures that can make a training run look successful while learning nothing at all, the detective work that traced a bug through nine discarded hypotheses to its root cause, and the paired experiment that proves this laptop-scale approach produces AI models statistically indistinguishable in quality from ones trained on enterprise supercomputers.
This isn’t just a story about optimizing code — it’s a story about what happens when a researcher refuses to trust a falling loss curve, and what that kind of scientific integrity means for who gets to build the future of AI.
Reference: Makazhan, A. (2026). Exact Layer Streaming: LoRA Fine-Tuning of an 8B Model on a 4GB Laptop GPU (v3). [ https://zenodo.org/records/21918325](https://zenodo.org/records/21918325)
Neutrino astronomy and the effort to build a cubic-kilometer-sized detector at the South Pole are recognized by the 2026 Nobel Prize in Physics.
This story will be updated with a longer explanation of the Nobel-winning work on Thursday, 8 October.
When it comes to messengers from space, neutrinos seem meager: Interacting only through the weak nuclear force, they barely register in Earthly detectors. But unlike cosmic rays and photons, neutrinos are neither deflected nor attenuated during their journeys and thus can deliver information that other astronomical messengers cannot. This year’s Nobel Prize in Physics recognizes the potential of neutrino astronomy and the assiduous efforts of Francis Halzen to bring it to fruition. Halzen, a particle physicist from the University of Wisconsin–Madison, was the leading force behind the IceCube Neutrino Observatory—a cubic-kilometer-sized detector operating in Antarctic ice since 2010. Shortly after its construction, Halzen and his colleagues reported the first evidence of neutrinos originating from cosmic sources [1, 2]. Further study of these astrophysical neutrinos may provide information about the powerful events that produce high-energy cosmic rays.