Toggle light / dark theme

Get the latest international news and world events from around the world.

Log in for authorized contributors

On Continued Gravitational Contraction

On September 1, 1939, the same day Germany invaded Poland, J. Robert Oppenheimer and his student Hartland Snyder published a five-page paper that would help lay the mathematical foundations of black-hole physics.

Their paper, “,” published in Physical Review, used Einstein’s general theory of relativity to show how a sufficiently massive star could collapse under its own gravity, contracting beyond its gravitational radius and becoming inaccessible to distant observers.

It was a remarkable theoretical result. Yet its arrival coincided with the outbreak of World War II, and the discovery attracted little immediate attention.

Oppenheimer would soon turn his attention to nuclear physics and the wartime effort that would eventually lead him to direct the Los Alamos laboratory. He never published another paper in astrophysics.

One of his most remarkable theoretical contributions was eclipsed by the very war that would ultimately define his career.

Utm_source=

#physics #oppemheimer

Beyond the Trial—What Do Extension Studies Add to Randomized Clinical Trials? Clinical Trials in Context

One critical shortcoming of many clinical therapeutic trials is their focus on short-term effects, leaving unanswered questions about how participants fare in the longer term. Trial extension studies are conducted to address this gap, allowing assessment of both durability of treatment benefit (eg, whether disease remission or improvements in function are maintained or diminished over time) and long-term safety (such as incidence of delayed adverse events).1 In therapeutic trials, extension studies can mitigate the ethical burden associated with discontinuation of potentially effective treatments or long-term administration of placebo or inferior interventions among those initially assigned to the control group.2 The prospect of an extension study may also give participants greater incentive to enroll in trials, despite concerns about being assigned to the control group in the initial phase of the research. Because extension studies build on existing trial infrastructure, they also allow additional and potentially valuable information to be derived from trials that already require significant up-front investment.

Despite these advantages, several key methodological challenges arise in the design and analysis of trial extension studies. The evidence from these studies is generally framed in the context of the original clinical trial, lending greater credibility to the quality of the outcomes data as well as any causal inferences about longer-term effects. However, epidemiologically, long-term extension studies are essentially cohort studies and, in many cases, uncontrolled cohort studies given the lack of any comparison group. Thus, when longer-term trial extension studies attempt to draw conclusions about the effects of study interventions, either favorable or unfavorable, the reader is often left wondering “Compared with what?”

Some extension studies follow up participants from only the original experimental treatment group. For example, in a study examining the long-term outcomes of intermittent paliperidone palmitate in adults with schizophrenia, investigators provided rare long-term data about outcomes after a trial in a population that is challenging to study3; however, participants who relapsed, died, or withdrew from the initial trial due to adverse events were excluded from the extension. As the investigators acknowledged in JAMA Network Open,3 this effectively created an enhanced cohort study with survivor bias and without a comparison group, limiting the statistical inferences that could be made. Investigators could not determine whether participants would have had similar outcomes even if they had not continued to be exposed to the intervention.
Abstract: 1 Chinese Institute for Molecular and Cellular Therapeutics, Chinese Institutes for Medical Research, Beijing, China

1 Chinese Institute for Molecular and Cellular Therapeutics, Chinese Institutes for Medical Research, Beijing, China.

2School of Basic Medical Sciences, Capital Medical University, Beijing, China.

Address for correspondence. Chuan-Yuan Li, PhD, Chinese Institutes for Medical Research, Beijing, China 100069. Email: [email protected].

Fractal patterns reveal hidden limits to AI predictability

Researchers at the University of Sydney have identified a fundamental mathematical reason why artificial intelligence systems can learn different behaviors even when trained under almost identical conditions, a discovery that could help improve the reliability and trustworthiness of AI technologies.

The study by Professor Pulin Gong from the School of Physics and his Ph.D. student Andrew Ly has been published in Nature Machine Intelligence.

As AI systems become increasingly embedded in health care, business, research and everyday life, ensuring they behave consistently and predictably has become a major challenge. The new research suggests that some forms of AI unpredictability are not due to engineering flaws or inconsistencies in computer hardware, but arise from the underlying mathematics of how neural networks learn.

ALIX Regulates Tumor-Mediated Immunosuppression by Controlling EGFR Activity and PD-L1 Presentation

(Cell Reports 24, 630–641; July 17, 2018)

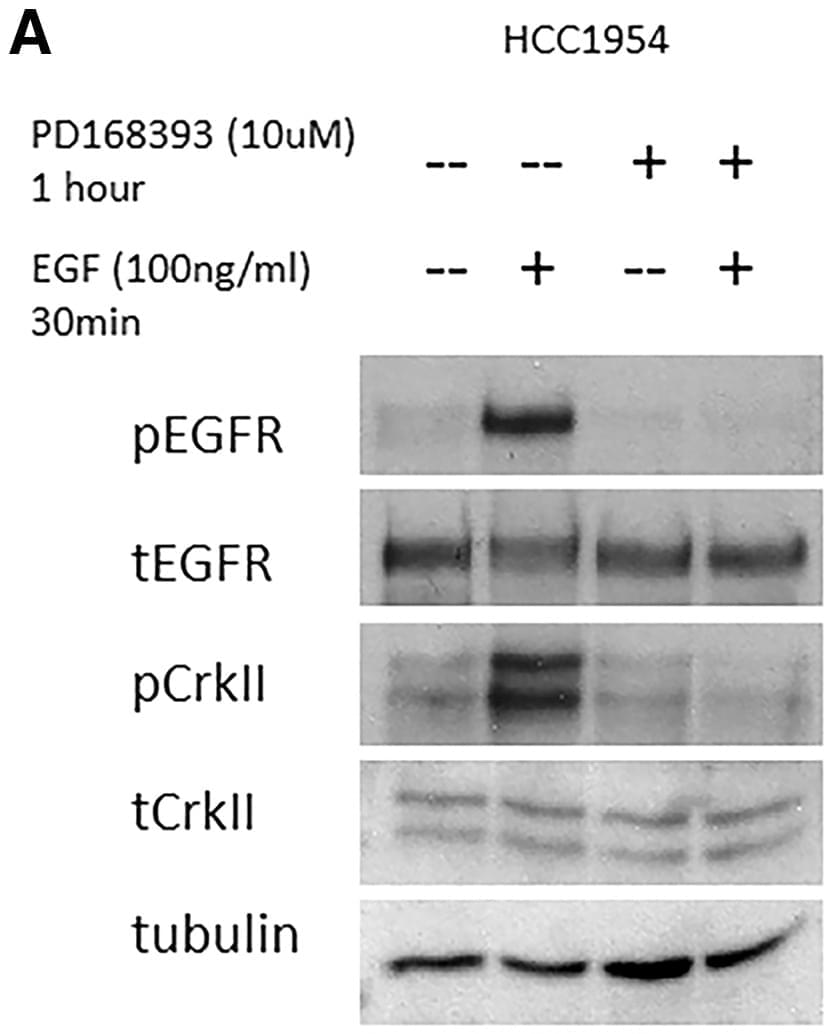
As published, blots showing the PD168393-sensitive, EGF-dependent phosphorylation of the CrkII-based Picchu-X biosensor in HCC1954 cells (Figure 1A) were inadvertently duplicated from an experiment showing the Mo-IPQA-sensitive, EGF-dependent phosphorylation of the CrkII-based Picchu-X biosensor in HCC1954 cells. This latter experiment was published as Figure 1B in PMID: 28166195.

Mo-IPQA is a PD168393 derivative, and figures for both papers were prepared concurrently, leading to the inadvertent duplication.

Experts Share Their Tips For Spotting If The ‘Person’ Calling You Is Actually AI

“A modern chatbot writes warm, clean, grammatically perfect text, often better than the average person in a hurry. If you are scanning for typos or robotic phrasing, you are using a 2022 test on a 2026 system,” he said.

“What has not been solved is consistency, specificity, and backbone.”

Instead, you need to think about speed and sentence shape. “Chatbots answer almost instantly, and every answer is roughly the same length and structure, neatly organised, often with a tidy summary at the end,” said Martynenko.