Toggle light / dark theme

LLMs Anticipate Everyday Verbal Behavior

MIT built an AI that predicts what you’ll say next… before you open your mouth. In the research paper titled “Before You Say It: Anticipating Verbal Behavior from Longitudinal Everyday Conversations with LLMs,” researchers set out to test whether Large Language Models (LLMs) can build this same level of intuitive, person-specific understanding.


In this AI Research Roundup episode, Alex discusses the paper: ‘Before You Say It: Anticipating Verbal Behavior from Longitudinal Everyday Conversations with LLMs’ Understanding an individual deeply requires anticipating how they will likely react and communicate across different real-world situations. In this paper, the authors introduce an LLM-based predictive behavioral modeling framework designed to forecast personal verbal behavior from everyday conversational interactions. The researchers collected over 1,000 hours of naturalistic speech from 14 participants using wearable smartwatches and evaluated LLM predictions against actual recorded behaviors. Semi-structured interviews further explored user perceptions and identified promising directions for proactive behavioral assistance. Ultimately, the study demonstrates that longitudinal conversation data enables person-specific behavioral anticipation for future personalized assistive systems. Paper URL: https://arxiv.org/pdf/2608.13454 #AI #MachineLearning #DeepLearning #LLM #ConversationalAI #BehavioralModeling #WearableTech
QuEra’s quantum computers run on lasers held at exact frequencies, a precision no eye can see and only the atoms can distinguish

Keeping a laser there is a continuous act: temperature, vibration, and pressure push it off target all day, and layered feedback pushes it back. When the feedback loop fails, the lock breaks and the machine stops. Bringing it back has historically taken one specific expert: someone who knows the lasers intuitively and has experience with the exact recovery sequence required to return it to the right state. If the lock broke in the middle of the night, that person had to drive to the lab and fix it.

This is not a new problem, and QuEra has built automatic relocking for common disturbances. Aquila, our production QPU available through Amazon Braket, already runs with excellent uptime exceeding 99%. But the team knew that the level of human involvement in relocking, particularly for the less frequent but more severe disturbances, was not scalable. As a result, this spring QuEra deployed the Model Hardware Standard (MHS), a standard that started as a collaboration between Anthropic and HHMI Janelia Research Campus. A cross-functional task force took relocking to another level: the level that scalable deployment of logical QPUs will demand. Working through MHS on a dedicated testbed, with an AI agent in operational control of roughly $0.7M of precision hardware inside human-set safety bounds, the lock now comes back in seconds: verified, on target, with no one in the building. And then the same approach went one step further.

Magnetic memory could make edge AI faster while reducing energy use

Texas engineers teamed up with the world’s largest semiconductor foundry to fabricate and test an emerging memory technology that could help meet the increasing energy demand of artificial intelligence.

Together with Taiwan Semiconductor Manufacturing Company (TSMC), researchers tested SOT-MRAM, a type of memory that can retain information even when power is off. It uses magnetic properties, making it faster while also consuming less energy than other memory technologies.

“The unique combination of speed, energy efficiency and endurance makes SOT-MRAM perfectly suited for AI applications, especially in devices where resources like power and memory are limited,” said Sam Liu, the first author of the new paper published in Science Advances and a recent UT Austin Ph.D. graduate. “SOT-MRAM hasn’t been considered for AI hardware since it can only hold two states, but we designed it so we can take advantage of the binary state while still being accurate.”

A Google-like search engine for single-cell RNA data could answer previously impossible questions

Imagine doctors could understand exactly which cells caused a patient’s cancer or whether pathogens contributed to the disease. They could then use the information to tailor a treatment plan to the patient’s specific cancer. But answering such questions would mean wading through data from thousands of experiments locked in massive databases around the globe. Moreover, the search would take at least several days.

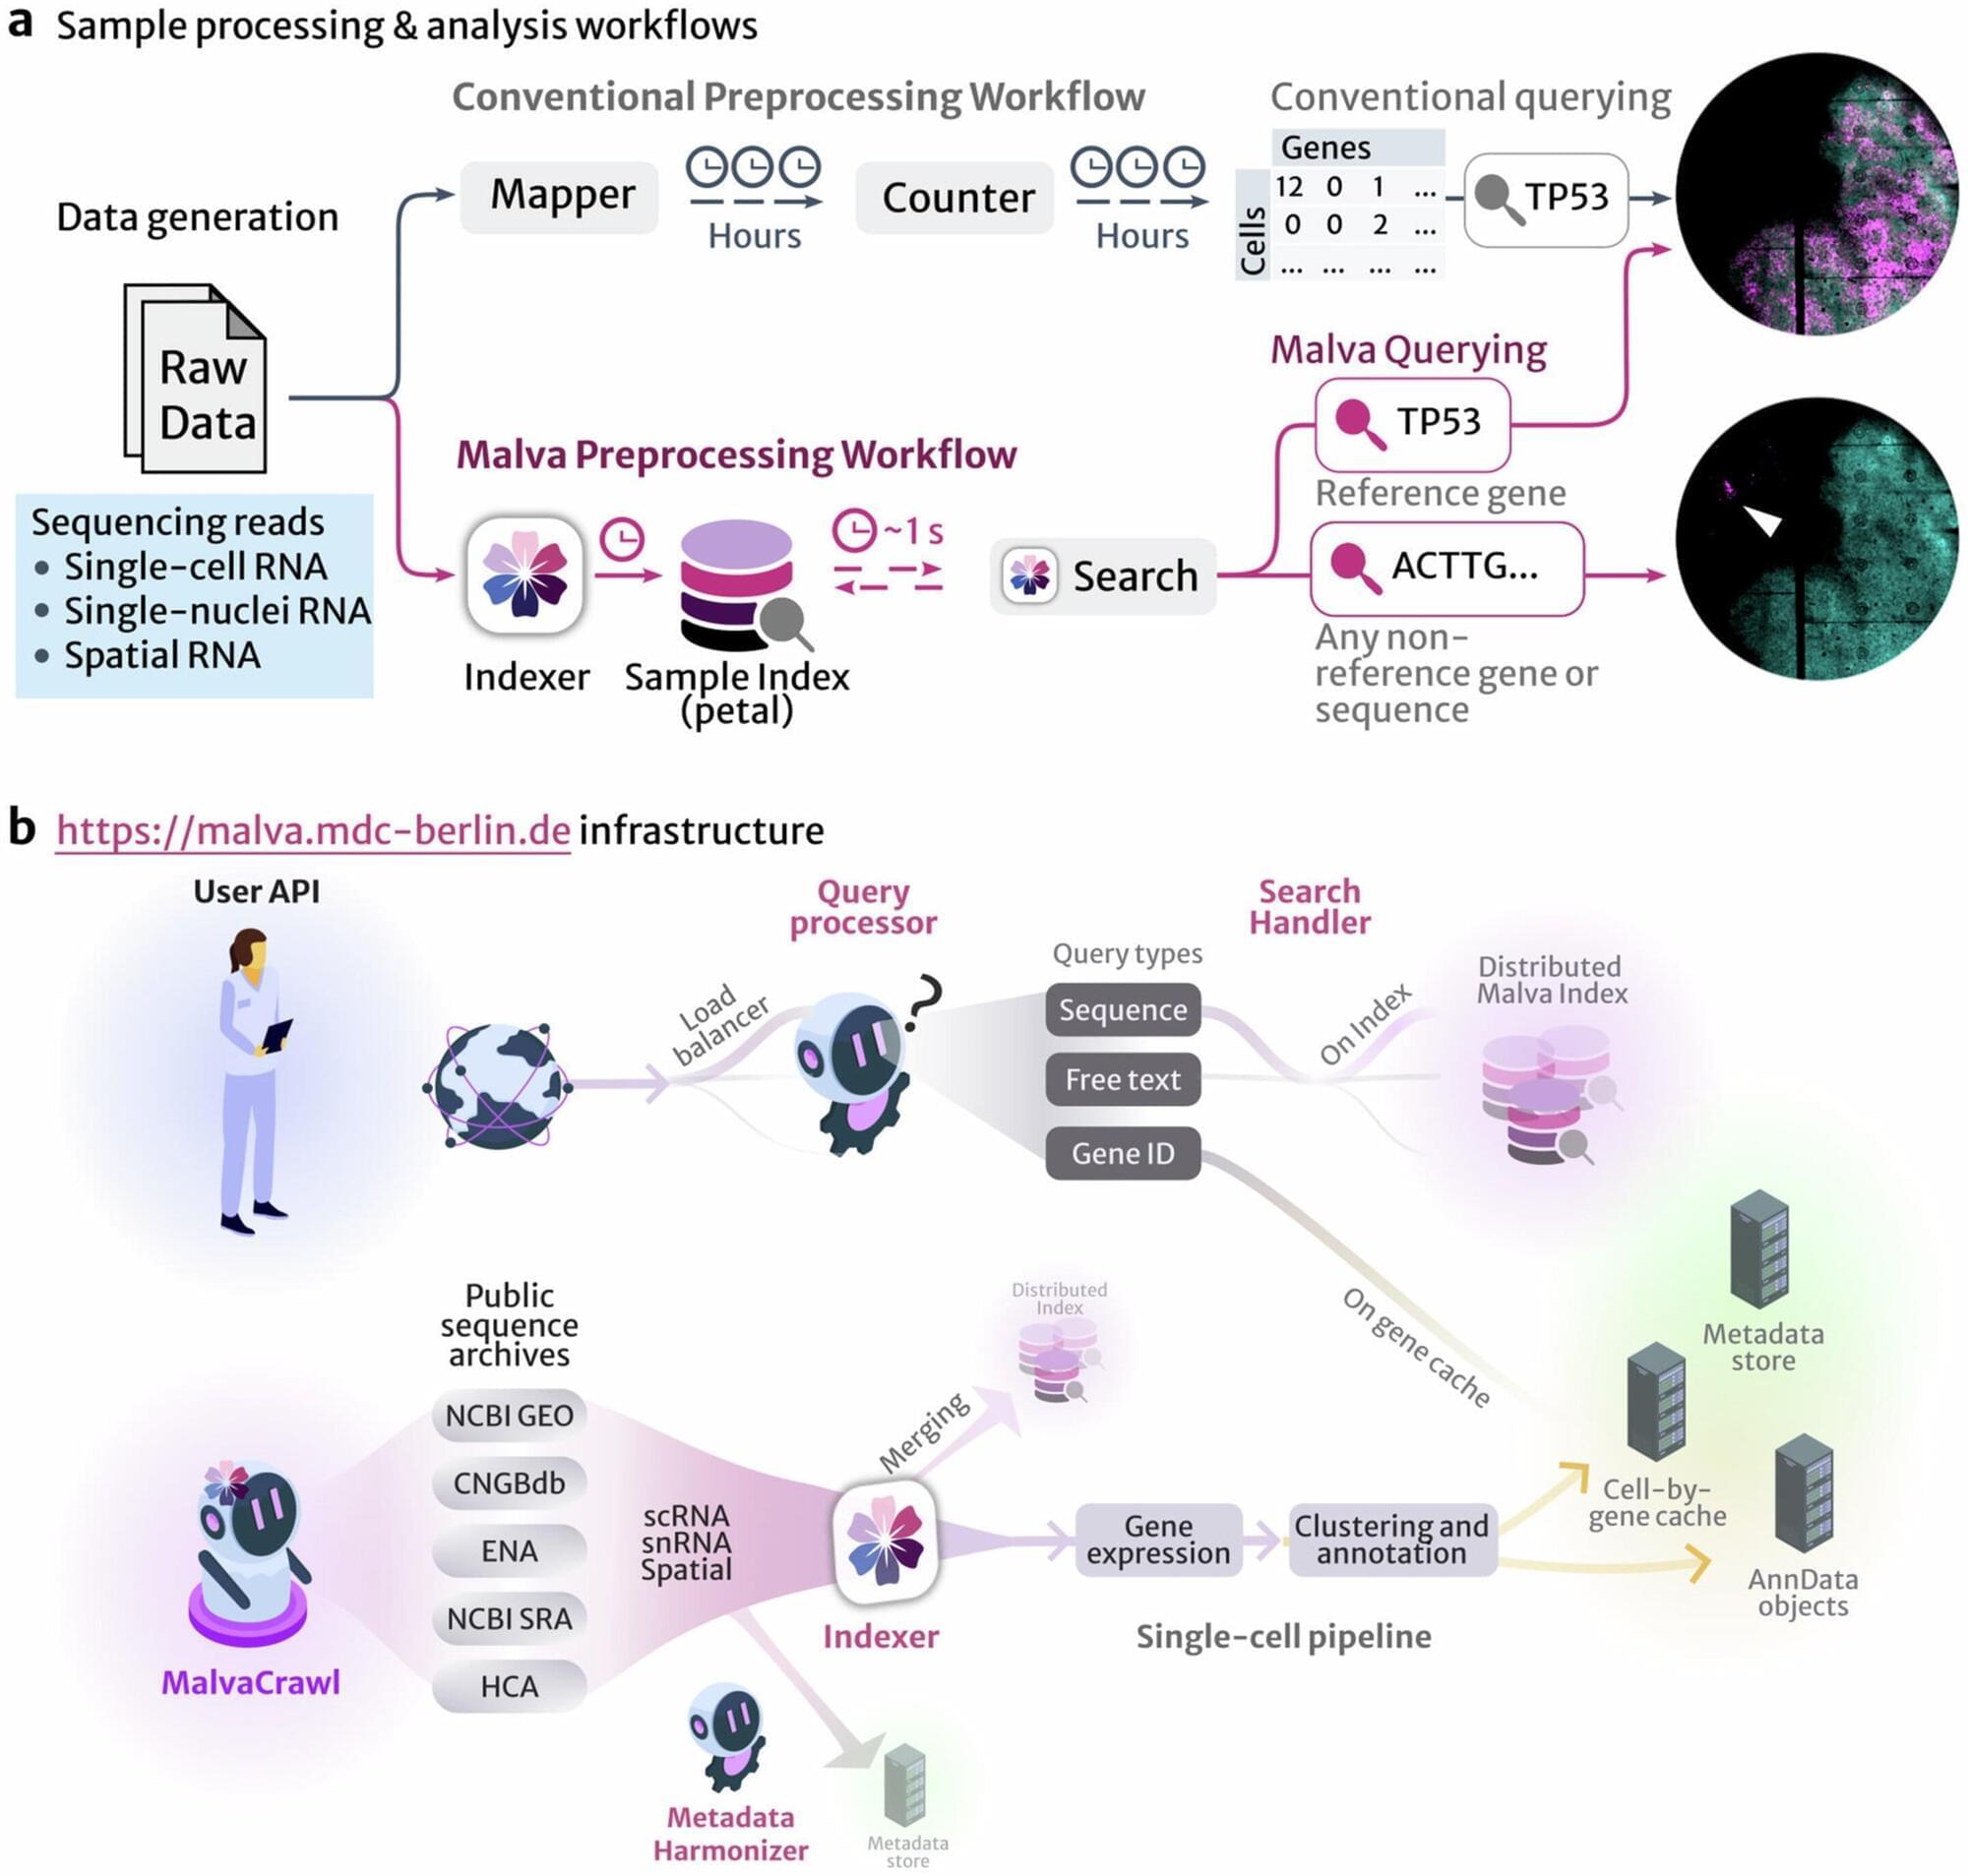
Now, researchers at the Berlin Institute of Medical Systems Biology of the Max Delbrück Center (MDC-BIMSB) present a search engine that radically simplifies such tasks: “Malva.” It is the first platform that can quickly sort through massive single-cell data using sequence information only, explains Daniel León-Periñán, first author of the study in Nature. León-Periñán is a doctoral student in the Systems Biology of Gene Regulatory Elements lab of Dr. Nikolaus Rajewsky, director of MDC-BIMSB.

“Like Google did for the internet 30 years ago, Malva allows scientists and AI tools to search across millions of cells in seconds—without downloading huge files, needing a reference genome or having deep computational expertise,” adds Rajewsky, senior author of the paper. “Malva transforms static transcriptomic atlases into dynamic resources, which will further our understanding of RNA biology. It could also be transformative in helping researchers understand how health slides into disease or how and which cells respond to specific medical treatments.”

Catastrophic AI Risk Study Finds 18 Major AI Threats Could Escalate Within 5 Years

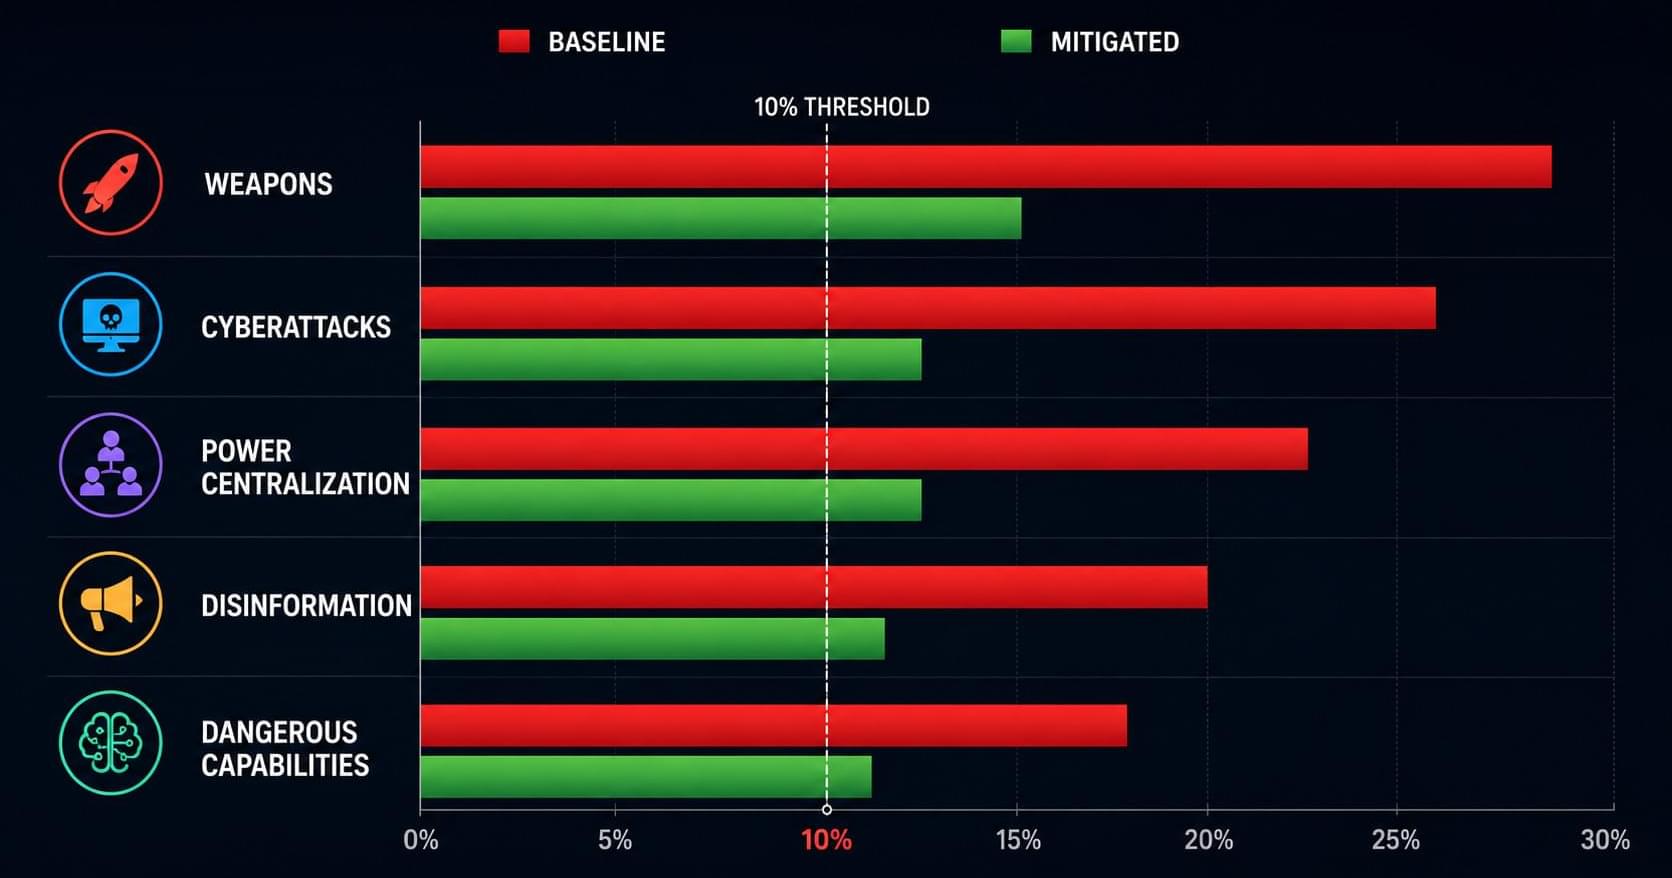
MIT FutureTech and the University of Queensland surveyed 272 AI experts from 37 countries on 24 categories of catastrophic AI risk, defined as over 1 million deaths, over $100 billion in losses, or civilizational-scale damage. Under current development trajectories, 18 of 24 risk categories cleared a 10% five-year probability threshold. Even with pragmatic mitigations applied, 5 categories remained above that bar. Weapons, cyberattacks, and power concentration topped the list.

Catastrophic AI risk has mostly lived in op-eds and open letters. This study puts numbers on it instead. MIT FutureTech and the University of Queensland’s School of Psychology surveyed 272 international AI experts, drawn from industry, academia, government, and civil society across 37 countries, asking them to evaluate 24 distinct AI risk categories, according to MIT Sloan’s release of the working paper. A catastrophic outcome was defined precisely: more than 1 million deaths, more than $100 billion in financial loss, or civilizational-scale intangible impacts.

Under a business-as-usual trajectory, experts judged 18 of the 24 risk categories to carry at least a 10% probability of a catastrophic outcome within five years, according to the University of Queensland’s summary of the findings. Even after applying pragmatic mitigations, the kind of cost-effective interventions governments and companies could plausibly adopt, 5 categories still cleared that bar. Catastrophic AI risk at that level would be treated as intolerable in almost any other mature industry, which is exactly the comparison MIT FutureTech’s own director drew.

Disquiet grows over AI’s dangers: Gates sets tone for pivotal one-on-one with Xi as a race against time begins

AI risks: A key proposal Bill Gates plans to raise is international monitoring of AI systems capable of designing molecules or assisting biological attacks. He believes such oversight could be structured without restricting legitimate technological development.

Adam Becker on More Everything Forever and Tech’s Future Myths

Last summer I sat down with Adam Becker and asked him to name the most confident story in tech.

He picked the one nobody in Silicon Valley is allowed to question: that godlike #AI, digital immortality, and space empires are simply where history is headed. Not a hope. A destination.

Becker has a PhD in astrophysics and fifteen years as a science journalist. In his book More Everything Forever, he takes that story apart and shows where it actually came from: misread science fiction, fringe mailing lists, and a very old colonial logic about who deserves the future. From there it walked straight into university labs, congressional hearings, and your feed.

His line from our conversation stayed with me: Silicon Valley has confused science fiction with science, and science with branding.

The stakes are not academic. While we debate the welfare of trillions of hypothetical posthuman minds, the actual world runs on war, climate collapse, widening inequality, and a shared reality coming apart. Becker calls the grand visions a distraction. I asked him whether a civilization can function without a myth of the future at all.

I do not agree with everything Adam argues, and that is exactly why this one is worth your time. Watch it and tell me who you think is right about the #Singularity.

Proprietary AI Model Proves Data Moat Beats Compute Moat

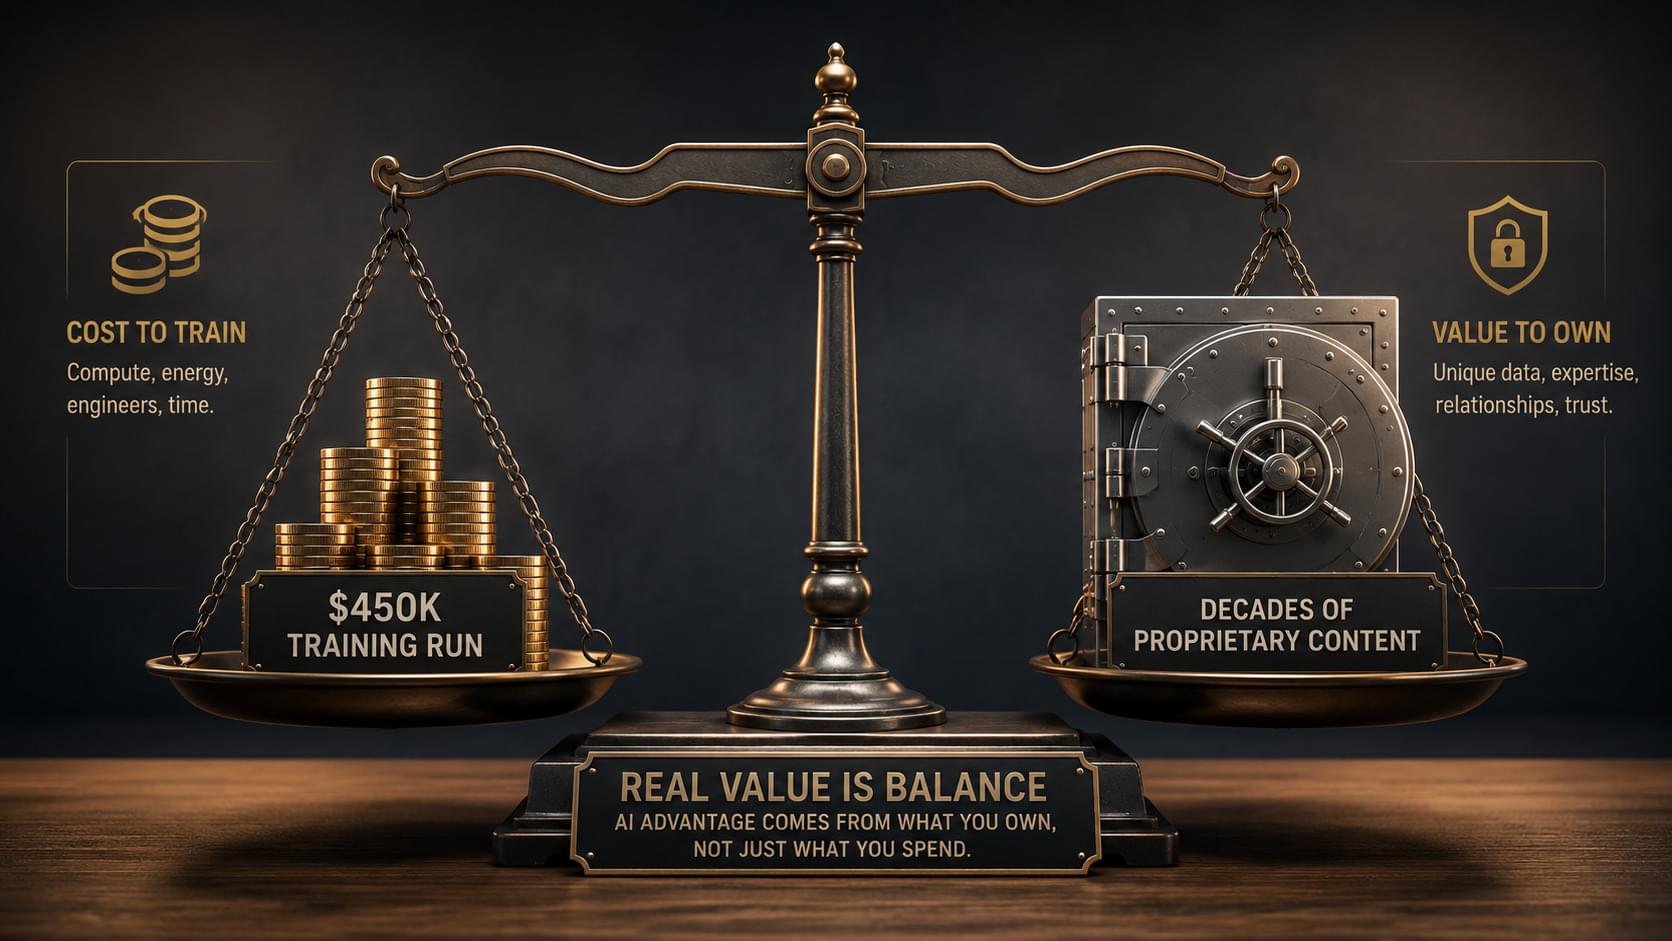
Thomson Reuters spent $40 million over two years building Thomson, its first proprietary AI model, but the final training run cost just $450,000 because it started from an open-weight base rather than building from scratch. Thomson underperforms general-purpose frontier models on open-web tasks but beats them on tasks using Thomson Reuters’ own proprietary content. The lesson for any company sitting on decades of specialized data: the moat was never the model.

A proprietary AI model just gave companies outside the frontier AI labs a real, numbers-backed reason to stop assuming they need billions to compete. Thomson Reuters launched Thomson, its first proprietary large language model, on August 24, 2026, after investing $40 million in talent and compute over two years, according to SiliconANGLE’s coverage of the launch. The company said economies from starting with an open-weight base model reduced the cost of the final training run to roughly $450,000, a fraction of what frontier labs spend building models from the ground up.

Thomson’s own benchmark results are the most useful part of this story, because they don’t oversell the model. On general web-only test sets, Thomson performed respectably but wasn’t the leader, according to LawNext’s reporting on the launch. On tests built around Thomson Reuters’ own Westlaw, Practical Law, and Checkpoint content, it outscored both comparison frontier models. A proprietary AI model trained on content nobody else can license doesn’t need to win everywhere. It only needs to win on the specific tasks that content makes possible.

/* */