Toggle light / dark theme

When microbial DNA is scarce, new profiling method helps separate genuine signals from contamination

In acute, life-threatening infections, rapidly characterizing the microorganisms in a patient sample can help guide diagnosis and treatment. Computational methods known as taxonomic profilers can analyze metagenome sequencing data generated from the microorganisms’ genomic information and compare it with reference genomes of individual microorganisms. However, taxonomic profilers are still under development and are not yet in common use. Current methods can produce false-positive results or inaccurate abundance estimates.

Researchers at the Helmholtz Centre for Infection Research (HZI) have developed a new taxonomic profiler called Metax. By using information about how sequencing reads are distributed across microbial reference genomes, Metax can distinguish true microbial signals from artifacts more reliably and improve both taxonomic identification and abundance estimation. The study was published in the journal Cell.

“In clinical samples, for example, microbial profiling can provide important information about microorganisms that may be relevant for an infection,” explains Alice McHardy, a professor and head of the research group “Computational Biology for Infection Research” at HZI. “Such information can complement established diagnostic approaches and help researchers and clinicians investigate potential pathogens. But taxonomic profiling is equally important far beyond clinical applications, from human microbiome research to environmental monitoring.”
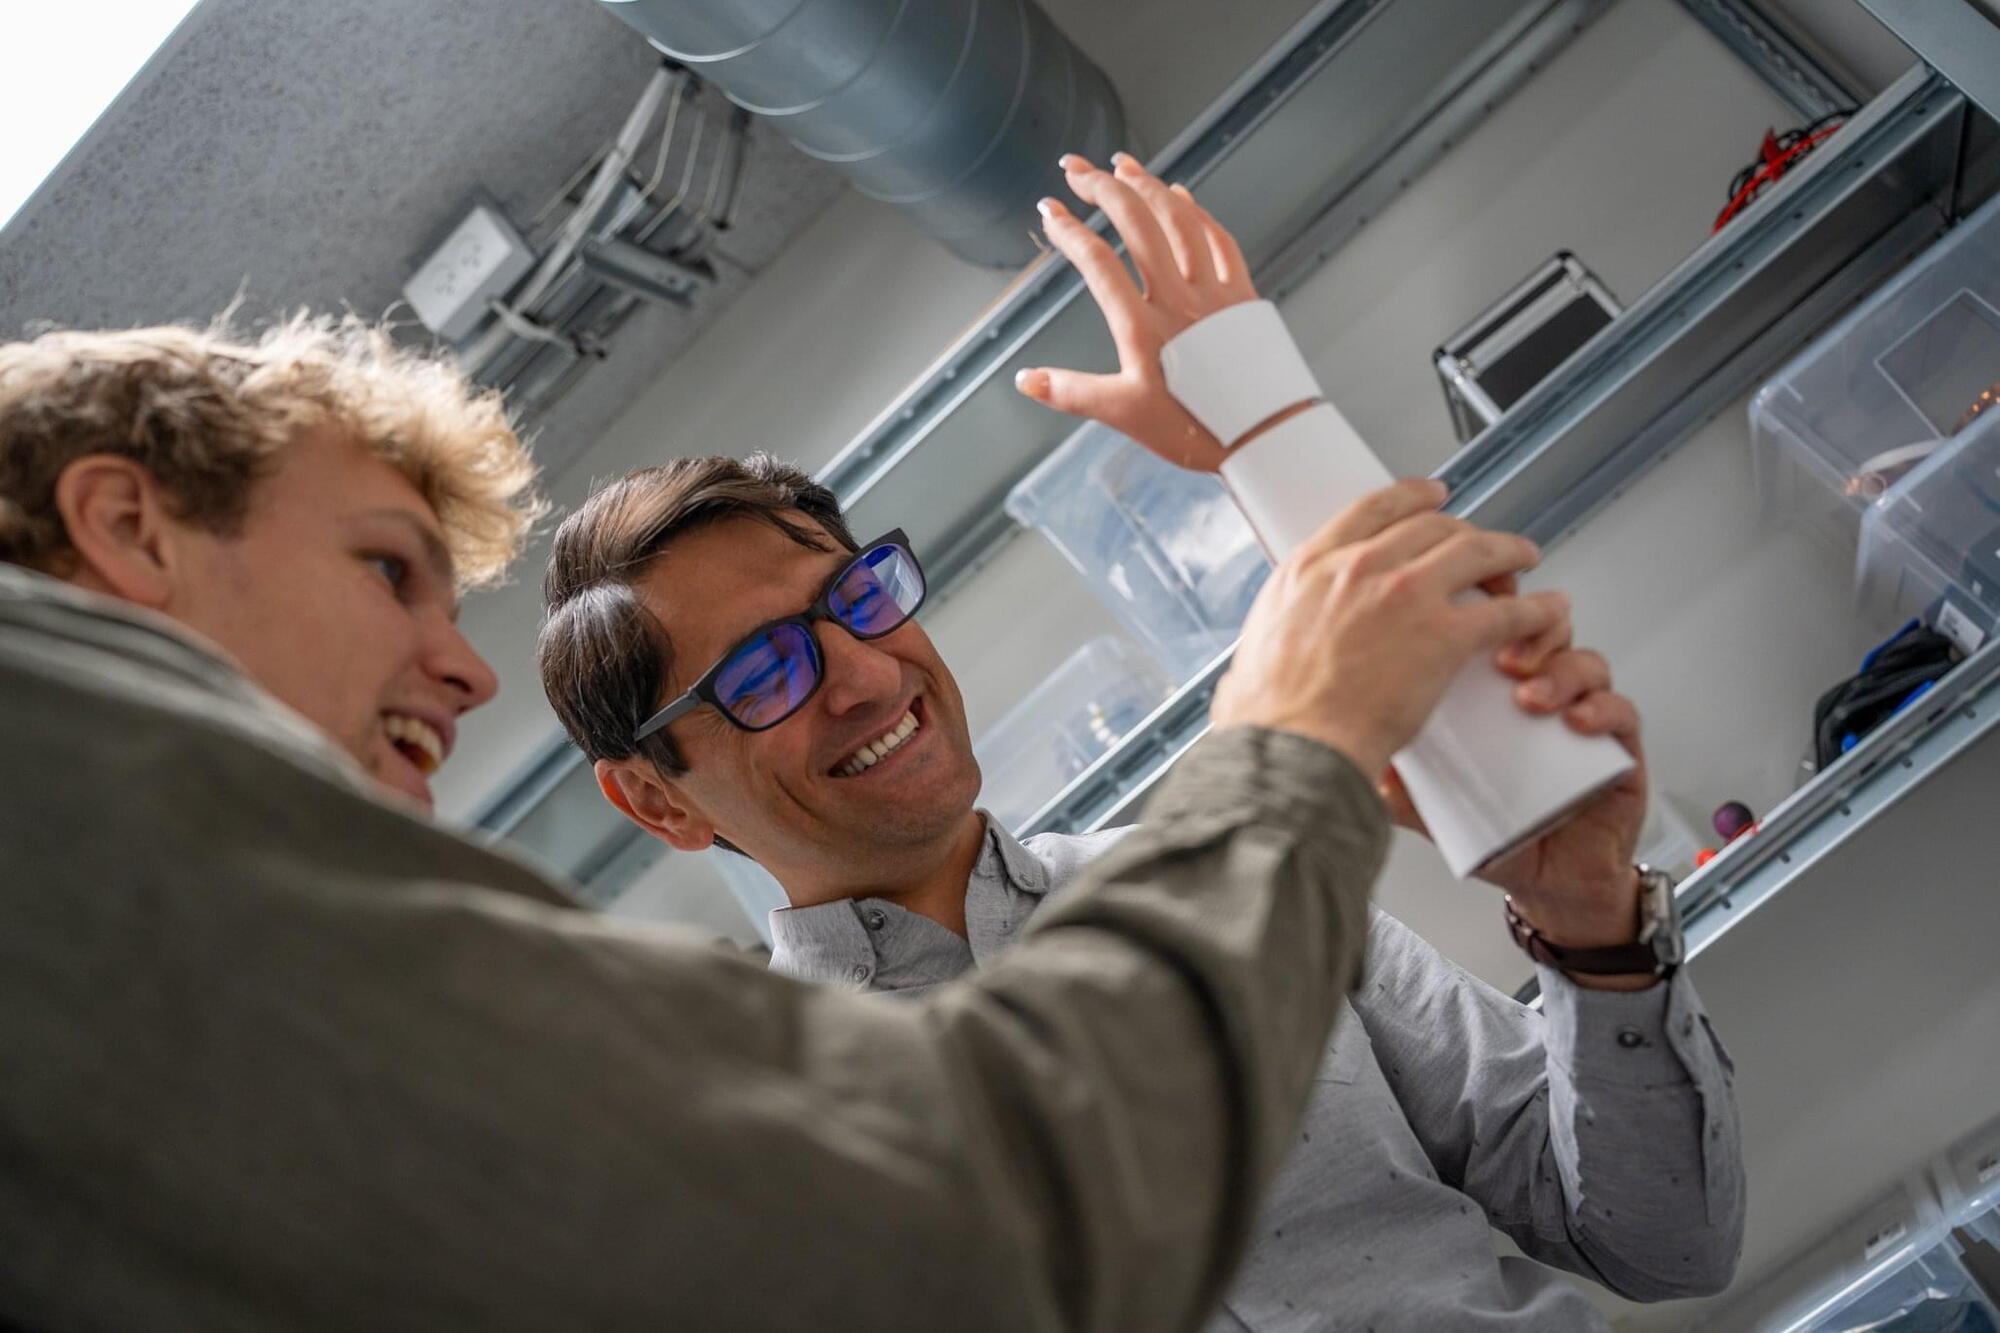
Saltwater sensor turns touch into electrical signals like skin, with prosthetic potential

You pick up a fragile glass from the table. Without thinking about it, you feel its surface against your fingertips and continuously adjust your grip. You hold it firmly enough to keep it from slipping out of your hand, but not so tightly that it breaks.

For you, this is a simple maneuver. But beneath the skin, you set off a sophisticated interplay of processes. The pressure from your fingertips opens tiny gates in the skin’s sensory cells, allowing electrically charged atoms to flow in. This shifts the electrical balance and triggers a nerve signal that travels toward the brain. There, the signal becomes part of the information that allows you to feel the touch and continuously adjust your grip.

Clever.

Hackers Use NeedyMantis to Maintain Long-Term Access in Breached Networks

Hackers have used a malware family called NeedyMantis to maintain long-term access to networks they had already breached, Microsoft said in a technical analysis.

The malware has been seen in a small number of targeted intrusions at telecommunications organizations, universities, medical nonprofits, intergovernmental organizations, and government contractors. Its use goes back to at least October 2025.

Microsoft found NeedyMantis while following up on indicators from Kaspersky’s investigation into the supply chain attack on DAEMON Tools. In that attack, official, signed installers for the DAEMON Tools Lite disk image program carried malicious code from April 8, 2026. The developer replaced them with a clean version on May 5.

Autonomous Lipid Nanoparticle Engineering

Researchers at the Massachusetts Institute of Technology have developed an automated production system for lipid nanoparticles (LNPs) that offers unprecedented control over their size and shape, significantly accelerating the design of targeted RNA and DNA therapeutics. While LNPs serve as crucial delivery vehicles for mRNA vaccines and other nucleic acids, traditional manufacturing relies on time-consuming trial-and-error and cannot reliably control particle dimensions, which dictate their behavior and targeted organs in the body. Building on a previously developed two-step fluid mixing technique, the newly autonomous platform integrates real-time dynamic light scattering to continuously monitor particle formation and adjust parameters on the fly. By leveraging data gathered from this automated system, the team also trained a machine-learning model capable of predicting the exact manufacturing conditions required to engineer LNPs with specific sizes and non-spherical shapes. This streamlined, data-driven approach eliminates previous manufacturing guesswork, providing a powerful tool to rapidly engineer customized delivery vehicles for next-generation genetic therapies.


Lipid nanoparticles (LNPs) are the leading vehicles for encapsulating and delivering nucleic acid therapeutics. Yet, their process development remains labor-intensive and empirical, constrained by coupled quality attributes and limited mechanistic insight. We present an autonomous, pilot-scale platform for accelerating LNP process development by identifying critical process parameters (CPPs) that produce LNPs with target size attributes. The platform combines a size-control production method with inline dynamic light scattering (DLS) for real-time feedback, enabling closed-loop experimentation and accelerated optimization. With built-in automated design of experiments, dynamic parameter sweeps, and Bayesian optimization, the platform enables rapid, data-rich exploration of complex design spaces.

Researchers find how prostate tumors reshape the immune microenvironment

Researchers at The University of Texas MD Anderson Cancer Center have identified a previously unknown pathway that prostate tumors leverage to suppress the immune system by reshaping the tumor microenvironment to resist treatment. A combined targeted therapy approach improved antitumor responses and prolonged survival in preclinical models of castration-resistant prostate cancer.

The study, published in Cancer Discovery, was led by Di Zhao, Ph.D., associate professor of Experimental Radiation Oncology, and Nicholas Navin, Ph.D., chair of Systems Biology. The findings suggest that tumors use this pathway as a backup physical defense and may explain why therapies targeting the B7-H3 immune checkpoint may show limited efficacy when used alone.

Our study shows that the immune checkpoint B7-H3 does more than put the brakes on the immune system; it also reshapes the cells surrounding a tumor to help cancer grow and resist treatment. By uncovering how this process works, we identified a promising strategy that combines B7-H3-targeted therapy with MEK inhibition. These findings could help guide more effective, personalized treatments for patients whose tumors are unlikely to respond to B7-H3 therapy alone.

Tissue-specific aging clocks map structured aging-modulatory drug-score patterns across 49 human tissue and cell-line categories

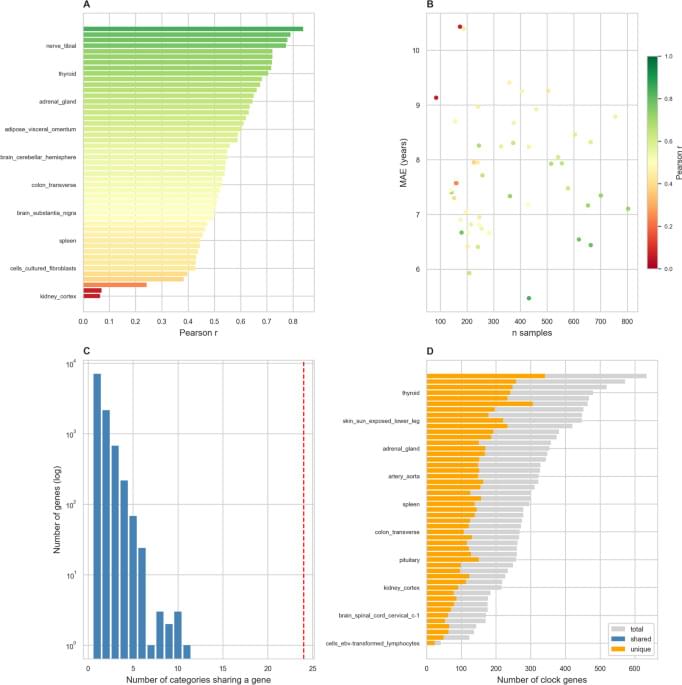
Aging clocks are typically trained on pooled multi-tissue data, implicitly assuming that aging is uniform across organs. Here we challenge this assumption by constructing 49 transcriptomic clocks across 47 tissue types and 2 cell-line categories from GTEx v8 (948 unique donors contributing to the retained clock categories) using donor-grouped cross-validation. Clocks achieved a median Pearson r of 0.543 (best: artery aorta, r = 0.855). We identified 10,253 unique clock genes, of which 69.2% appeared in only one tissue; however, null simulation confirmed that this low overlap is the expected consequence of sparse elastic-net selection rather than biological tissue-specificity. We then projected 3,926 LINCS L1000 compound-name entries onto each clock to build a drug × category age-reversal matrix. At a permissive threshold (|score|> 1.0), 94.2% of drugs showed mixed score directions (positive in some categories and negative in others). This permissive mixed-direction proportion was descriptive and did not itself exceed shuffled expectations. Under a more stringent exploratory criterion requiring |score|> 2.0 in at least three categories in each direction, 2.8% of compound entries showed pronounced bidirectional divergence, compared with approximately 0.1% under the shuffled null. Compound rankings remained stable when analysis was restricted to the 34 clocks with r ≥ 0.5 (Spearman ρ = 0.897 versus the full analysis). A Jaccard-based enrichment statistic yielded highly concordant compound rankings (median per-category Spearman ρ = 0.961), indicating that results were not artifacts of the enrichment method. After Benjamini–Hochberg FDR correction across all 192,374 drug-category pairs, only 0.79% reached FDR < 0.05, indicating that individual drug-category calls require caution. Rapamycin showed net pro-aging transcriptional signatures in our system; we explicitly emphasize that transcriptome-based scores and organismal lifespan are distinct endpoints. DepMap CRISPR analysis was repeated after GTEx-based standardization across 13 matched categories, although individual gene-level results were limited. Four statistical robustness tests confirmed model stability. These findings describe category-associated drug-score patterns and provide a tissue-aware resource for generating hypotheses about drug responses, while cautioning against over-interpretation of individual drug-category predictions without experimental validation.

A Deep‐Learning Based Biomarker of Systemic Cellular Senescence Burden to Predict Mortality and Health Outcomes

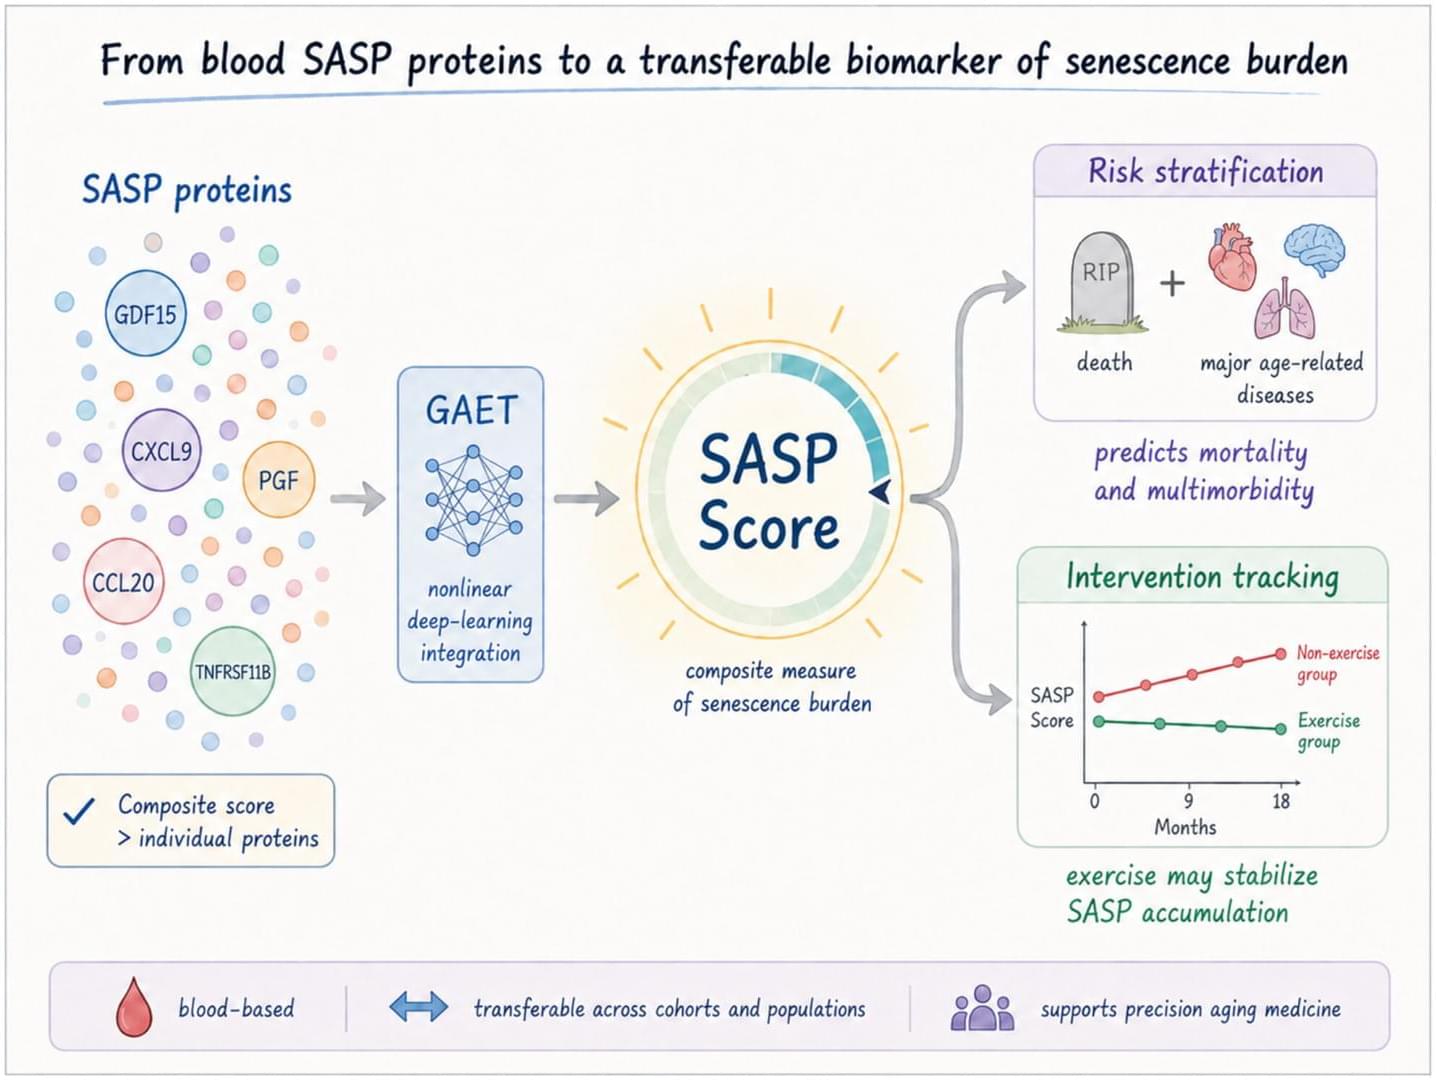
Spearman correlation coefficients were calculated between the SASP Score and chronological age, biological aging measures—including telomere length, proteomic aging clock (PAC) (Kuo et al. 2024), healthspan proteomic score (HPS) (Kuo et al. 2025), biological age (BioAge) (Sayed et al. 2021), phenotypic age (PhenoAge) (Diniz et al. 2017)—as well as other baseline aging traits including a 49-item frailty index (Williams et al. 2019) in the UK Biobank test sample. Details on the development of these biological aging measures are provided in the cited references, and the field IDs used to extract the relevant data are listed in Table S1.

The distribution of the SASP Score was compared across subgroups based on a common disease risk factor, including age group, sex, frailty status, waist-to-hip ratio group, and smoking status. Group differences were assessed using Wilcoxon rank-sum tests, with p-values adjusted for multiple testing using the Benjamini-Hochberg false discovery rate (FDR) method (Benjamini and Hochberg 1995). Additionally, the SASP Score distributions in subgroups were visualized using violin plots.

Cox proportional hazards models were used to investigate the associations of the standardized SASP Score with mortality and multiple aging-related diseases during follow-up (censored at death, or the last follow-up date of hospital inpatient data, whichever occurred first), with adjustments for baseline covariates. Mortality was ascertained through linkage to national death registries, and disease outcomes were derived using the UKB first occurrence data, which integrate multi-source data based on ICD-10 codes. Baseline covariates—including age, sex, ethnicity, education level, Townsend deprivation index (higher values associated with more material deprivation), smoking status (never, previous, current smoker), alcohol drinker status (never, previous, current drinker), systolic blood pressure, and BMI—were collected from UK Biobank online questionnaires or physical measurements at the baseline assessment. UK Biobank field IDs used to extract covariates and outcomes are provided in Table S1. Hazard ratios for each condition per SD increase in the SASP Score were reported with the multiple testing adjusted p-values using the FDR method. Model discrimination was evaluated using Harrell’s C-index, and the 95% confidence intervals were computed using a normal approximation based on the standard error of the C estimate.

RNA-Based Gene Editing Tool Combats Diseases With Multiple Mutations

Investigators from Mass General Brigham and Beth Israel Deaconess Medical Center have developed STITCHR, a new gene editing tool that can insert therapeutic genes into specific locations without causing unwanted mutations. The system can be formulated completely as RNA, dramatically simplifying delivery logistics compared to traditional systems that use both RNA and DNA. By inserting an entire gene, the tool offers a one-and-done approach that overcomes hurdles from CRISPR gene editing technology—which is programmed to correct individual mutations—offering a promising step forward for gene therapy. Results are published in Nature.

“CRISPR has revolutionized how we think about gene editing, but it has limitations. CRISPR can’t target every location in the genome, and it can’t fix the thousands of mutations present in diseases like cystic fibrosis,” said co-senior author Omar Abudayyeh, PhD, an investigator at the Gene and Cell Therapy Institute (GCTI) at Mass General Brigham and Engineering in Medicine Division in the Department of Medicine at Brigham and Women’s Hospital (BWH). “When we started our lab, one of the big things we wanted to figure out was how to insert large pieces of genes, or even entire genes, to replace faulty ones. This would allow us to target every mutation for a disease with a single gene editing construct.”

STITCHR harnesses the power of enzymes from genetic elements called retrotransposons, which are found in all eukaryotic cells, including animals, fungi, and plants. They are often called “jumping genes” for their tendency to move around and insert themselves into the genome. The researchers recognized how the copy-and-paste mechanism they use to move could be repurposed to edit genes at specific locations.

Wearable sensor metrics, AI, and context

“No one ever made a decision because of a number. They need a story.—Daniel Kahneman.

An essay from WSJ (gift link) https://wsj.com/opinion/when-ai-tells-a-story-about-your-hea…_permalink.

As health-tracking devices (like Oura rings, Whoop bands, and continuous glucose monitors) proliferate and generative AI becomes better at interpreting data, companies promise to turn personal measurements into actionable health insights. However, while AI excels at turning complex, ambiguous data into compelling personalized stories, there is a significant risk that these narrative health insights offer false precision—making recommendations feel far more reliable and individualized than the actual evidence supports.

1. Biology vs. Upstream Metrics.

Just as drug trials targeting specific biomarkers (e.g., lowering inflammation or Lp(a) levels) don’t always reduce overall disease or mortality, tracking upstream metrics (like glucose spikes in non-diabetics or sleep/readiness scores on wearables) often relies on unvalidated formulas with little proof that acting on them improves long-term health.

* AI works spectacularly in constrained biological problems (like AlphaFold predicting protein structures), but predicting holistic human health outcomes remains far more complex.

2. The Danger of AI Storytelling.

* Quoting Daniel Kahneman, “No one ever made a decision because of a number. They need a story.” Generative AI excels at connecting disparate data points (e.g., your HRV, sleep length, workout mileage, and stress levels) into plausible, persuasive narratives.

/* */