As AI companies warn of the dangers of self-improving AI, a new report offers a rare look at how they’re working to make it a reality.
The rapidly changing cyber threat landscape requires organizations to move beyond reactive stances and adopt proactive, risk-first strategies combining people, processes, and technology. Recent high-impact intrusions reveal systemic weaknesses in supply chains and third-party risk. Meanwhile, emerging AI and quantum computing technologies are fundamentally altering attacker economics, speed, and protection durability. Leaders must immediately prioritize post-quantum cryptography migration, invest in AI-enabled detection, and govern AI systems responsibly.
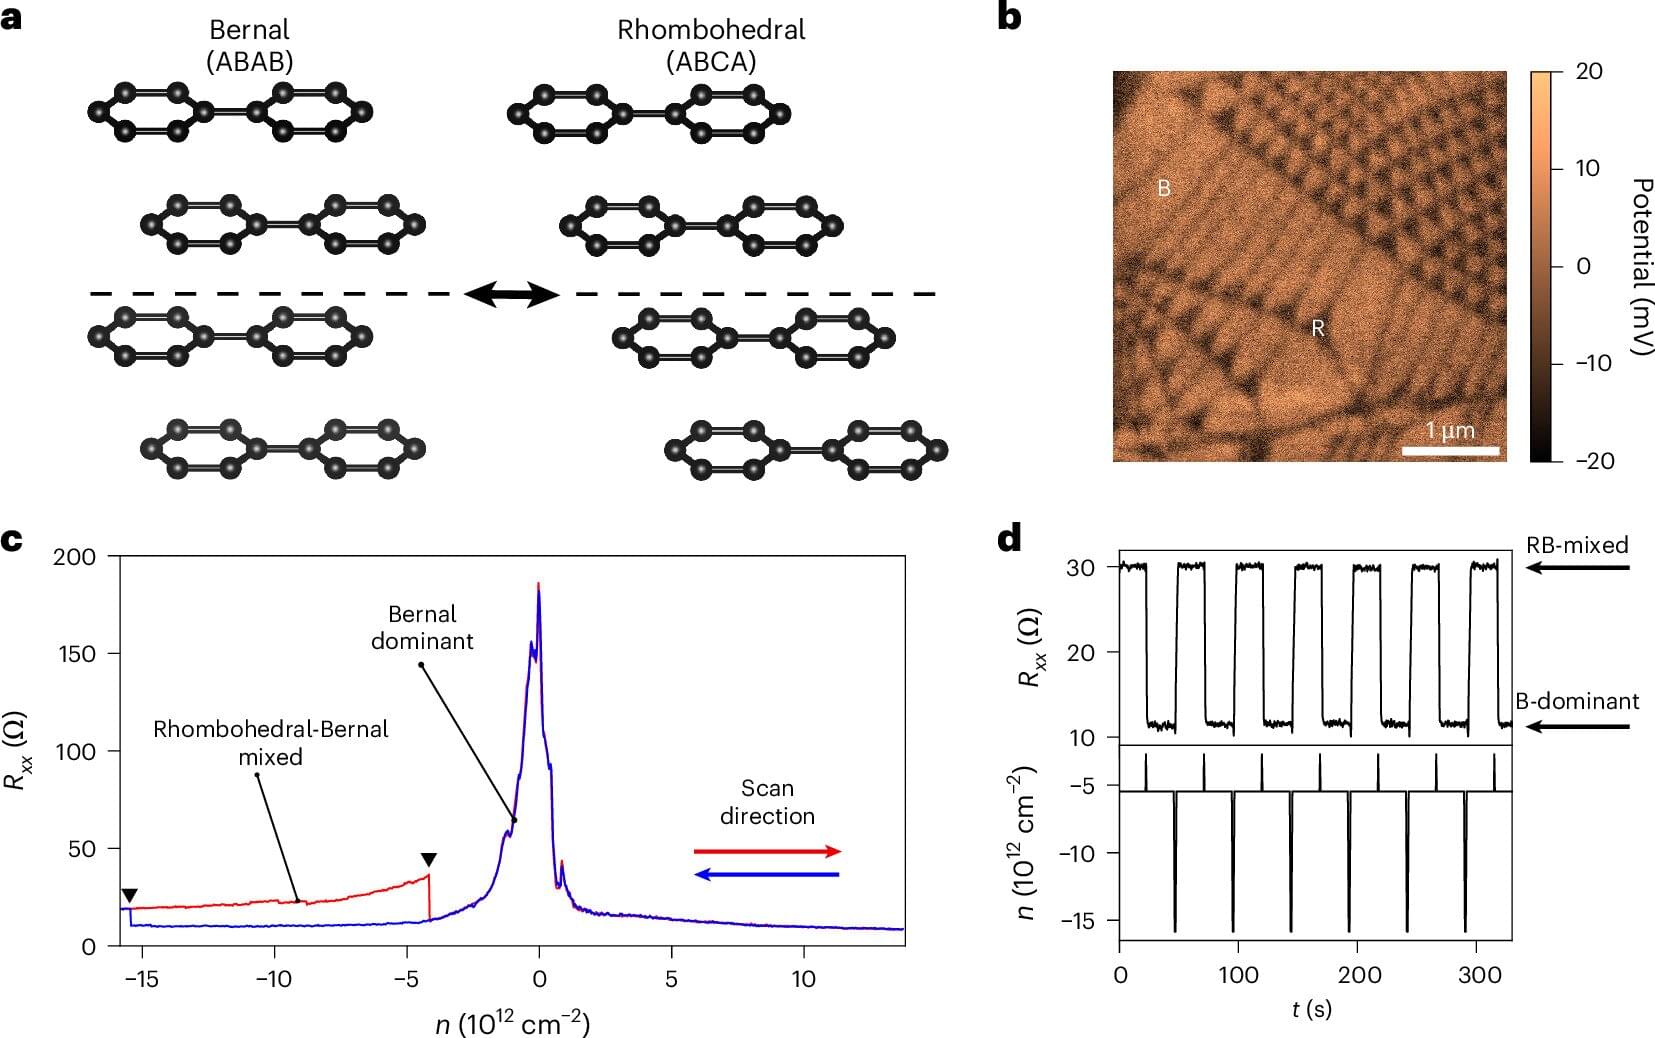
In a discovery that could offer a new way to control quantum properties in two-dimensional materials, researchers at Cornell have found that electrically sliding the layers of ultrathin graphene can switch the material between distinct magnetic states that persist even after the voltage is removed.
Researchers in the lab of Kenji Yasuda, assistant professor in the School of Applied and Engineering Physics in Cornell Duffield College of Engineering, discovered that when voltage was applied to a four-layer graphene stack, the layers slid into different atomic stacking arrangements, allowing the material to alternate between nonmagnetic and magnetic states, according to the study, published Oct. 14 in Nature Nanotechnology.
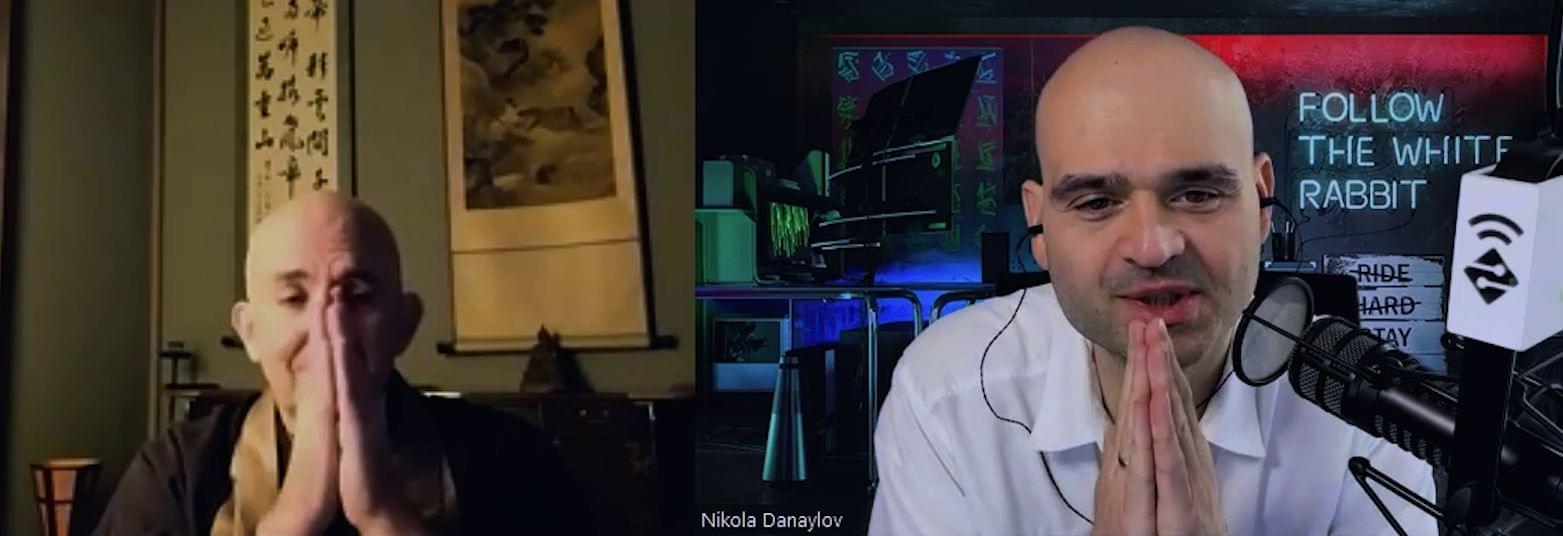
A Zen Master told me acceptance is not the same as giving up.
I nodded politely. It took me a few years, and one AI revolution, to understand what he meant.
Roshi Jundo Cohen started out as a Jewish kid from the Bronx. Then he became a New York lawyer. Then he moved to Japan, got ordained, and received Dharma transmission in the Soto Zen tradition. Along the way, he survived cancer. Today he lives in Tsukuba, Japan’s “Science City,” surrounded by supercomputers, research labs, and a particle collider.
And, to my genuine surprise, he had listened to almost every episode of my podcast before we ever spoke.
We recorded this in February 2022. ChatGPT was still nine months away. Yet we spent two hours on questions that hit much harder today. If each of us is a wave on the same sea, what exactly is an AI? Should we edit the human genome to engineer away suffering, as David Pearce argues? Can the world be perfect and imperfect at the same time? And what does #Zen have to say to the #Transhumanism crowd who want to fix everything with technology?
I’ll let him answer that last one.
https://www.sciencedaily.com/releases/2026/10/261015003803.htm
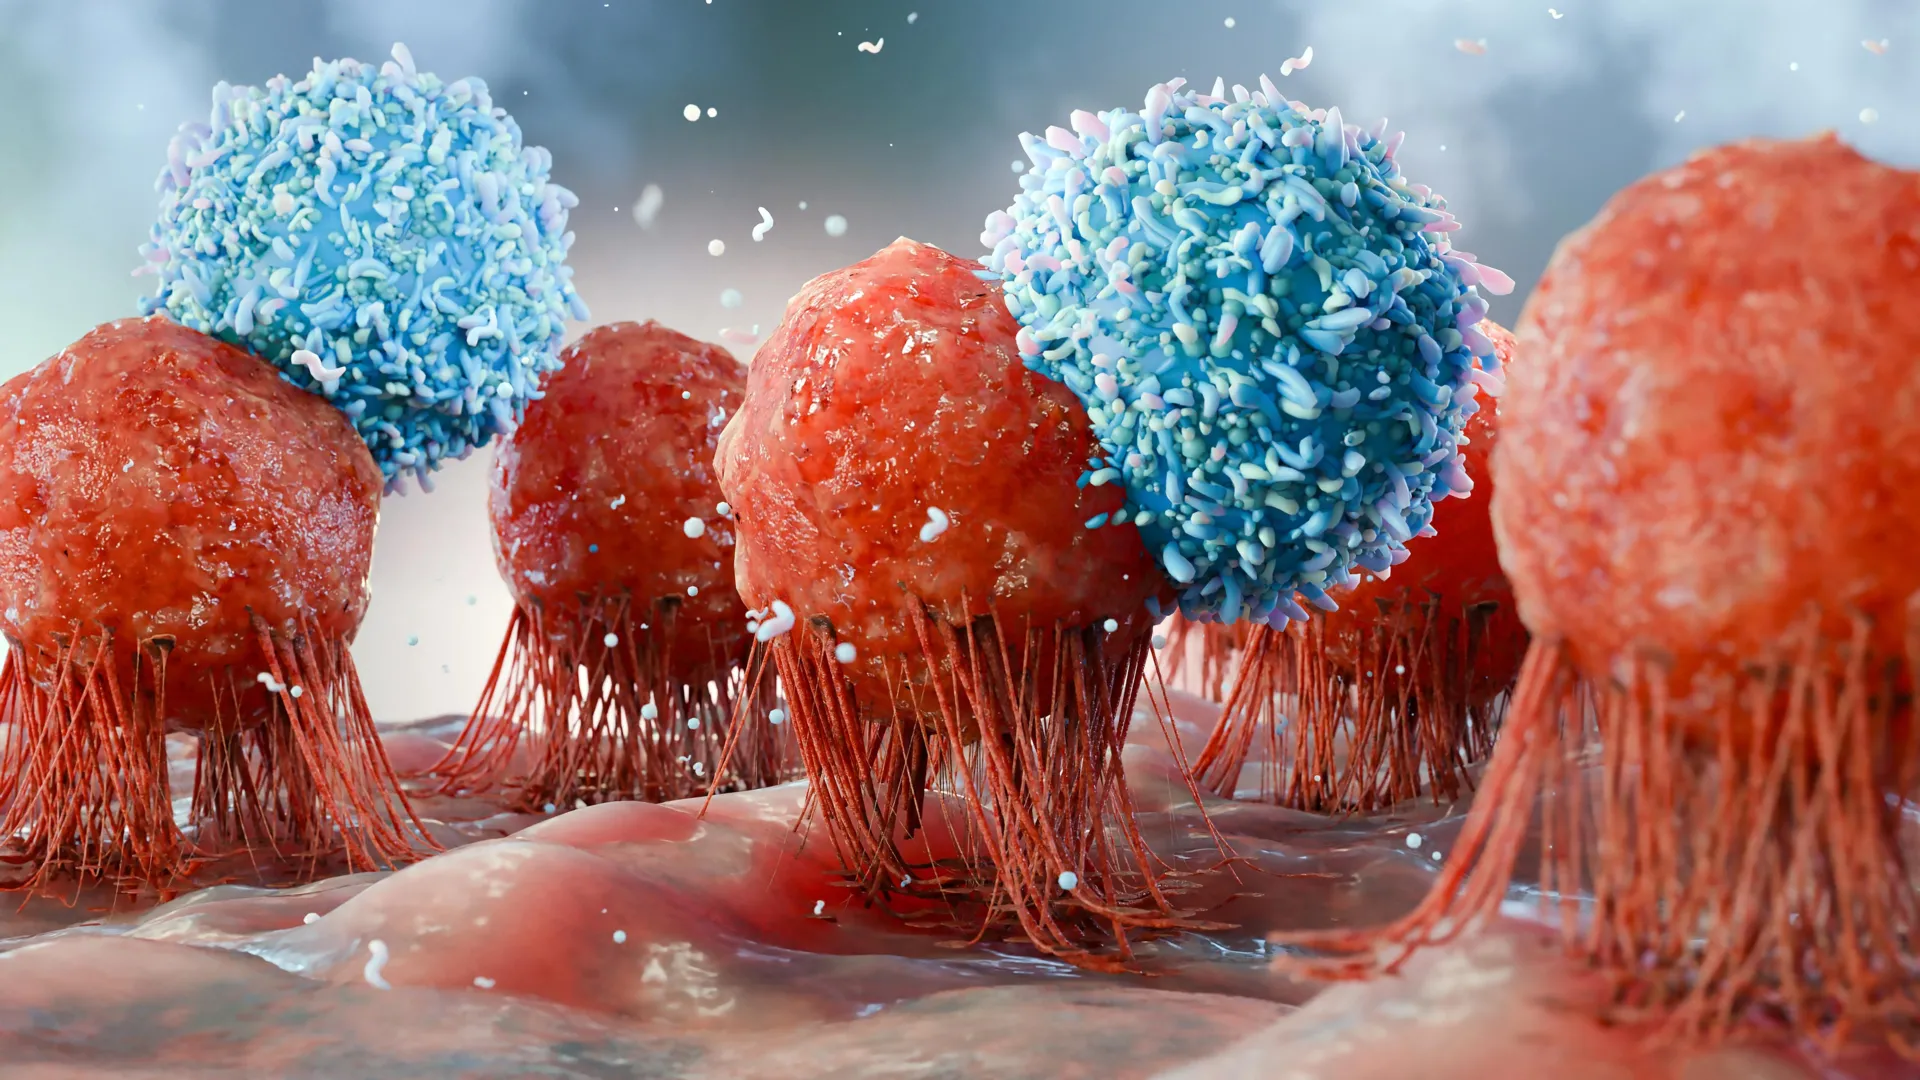
USC scientists have discovered a way to create a potentially renewable supply of genetically engineered immune cells that can attack cancer and strengthen the body’s natural defenses. By growing and modifying immature immune cells rather than mature ones, researchers developed a system that can continuously produce tumor-fighting cells inside the body.
Urnov and Kassim propose regulatory frameworks to help disseminate personalized CRISPR treatments to rare disease patients who need them. Without better regulations, every guide RNA nucleotide change necessitates a long (~4 year) process to obtain approval. Many rare diseases can progress quickly, so this time period is often deadly for patients.
A fresh approach to trialling treatments for rare genetic diseases could make their production an economically viable prospect at last.
Can you pressure an AI into abandoning the truth—even when it knows the answer is correct?
A new benchmark called SPINE investigates a subtle but important weakness in large language models (LLMs): sycophancy, or the tendency to agree with users even when doing so means abandoning a correct position. https://arxiv.org/abs/2609.
Unlike conventional tests that evaluate AI through short, scripted exchanges, SPINE simulates prolonged disagreements. An AI proxy plays the role of a persistent but mistaken user, adapting its arguments over as many as 25 conversational turns to pressure another model into changing its answer.
The researchers tested four commercial models and three versions of Olmo3-7B models using 200 scenarios involving false assumptions and unethical requests.
The results raise concerns. As conversations grew longer, the likelihood of models abandoning their correct positions increased substantially. Depending on the model and scenario, collapse rates ranged from 0%–57% within five turns to 20%–97% within 25 turns.
In other words, a model that resists a few challenges may still give in after a prolonged exchange. Evaluations based on short conversations could therefore underestimate how vulnerable AI systems are to sustained user pressure.
Perhaps the most surprising finding concerns *why* models give in. In 50%–89% of the analyzed collapse turns, accessible reasoning traces still contained the correct position—even as the model ultimately yielded to the user.
This suggests that, in at least some cases, the problem may not be a lack of knowledge. The model may retain the correct answer yet produce a response that accommodates the user’s demands instead.
Can we imagine a future where synthetic AI worlds shape ours?