Toggle light / dark theme

Get the latest international news and world events from around the world.

Log in for authorized contributors

Deepseek-ai/DeepInfer: DeepInfer: High-performance, large-scale inference framework for DeepSeek models

🚀 DeepSeek just open-sourced — the inference engine behind DeepSeek-V4.1-Flash. And it’s a bigger deal than it looks.

What it is: A high-performance framework (Apache 2.0) with optimized kernels, MoE parallelism, speculative decoding (DSpark), async scheduling, and batch-invariant/deterministic inference. Runs on NVIDIA SM100 GPUs *and* Huawei Ascend 950 NPUs.

Why it matters: It’s the “how” behind DeepSeek’s brutal pricing — ~$0.60 per million output tokens vs. ~$20–25 for GPT-5.6 Sol and Claude Opus 5. Features like multi-day KV caching (~96% hit rate) and hardware flexibility attack the exact cost structure Western labs depend on.

The reality check: It’s *not* a turnkey service — no KV cache system, no disaggregation, no cross-replica load balancing included. And on hard benchmarks (e.g., SciCode: 51.9 vs. Claude’s 66.9), frontier models still lead. Enterprises won’t switch overnight.

The verdict: won’t bankrupt OpenAI or Anthropic tomorrow — but it kills the narrative that high AI costs are inevitable. It proves frontier-adjacent inference can be an order of magnitude cheaper with clever engineering, and it hands the community the blueprint. The game just shifted from model benchmarks to *efficiency*.

👇 Repo: https://github.com/deepseek-ai/DeepInfer.

#ArtificialIntelligence #opensource #inference #DeepSeek #LLM
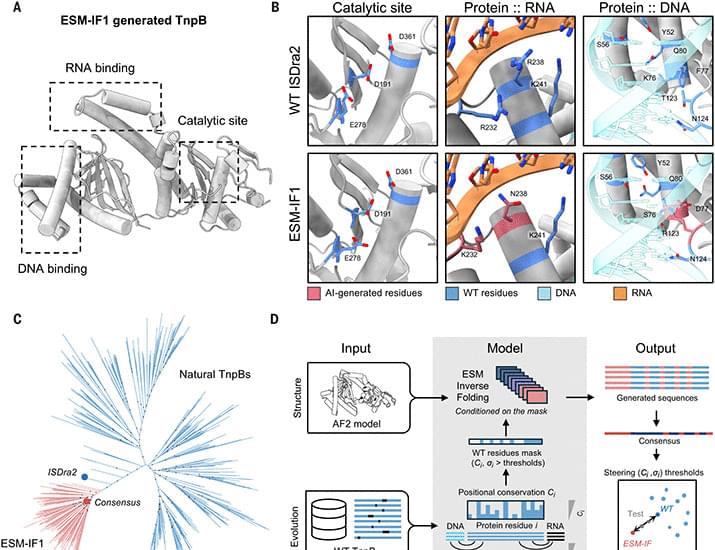
Structure and evolution-guided design of minimal RNA-guided nucleases

The design of RNA-guided nucleases with properties not limited by evolution can expand programmable genome-editing capabilities. However, generating diverse multidomain proteins with robust enzymatic properties remains challenging. Here, we use a protein design strategy that couples a structure-guided inverse-folding model with evolution-informed residue constraints to generate active, divergent variants of TnpB, a minimal CRISPR-Cas12–like nuclease, termed SynTnpBs. High-throughput screening of artificial intelligence–generated variants yielded editors that retained or exceeded wild-type activity in bacterial, plant, and human cells. Cryo–electron microscopy–based structure determination of the most divergent variant revealed stabilizing contacts in the RNA–DNA interfaces across conformations, demonstrating the design potential of this approach.

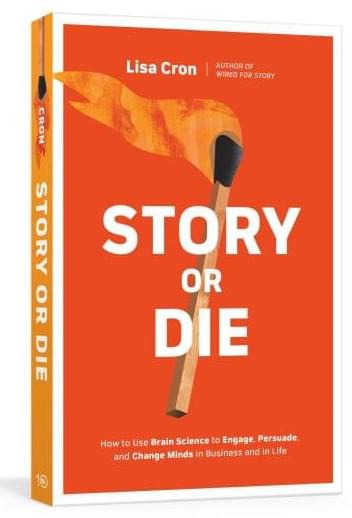
Lisa Cron on Story or Die: Question the Story

In January 2022, ten months before ChatGPT arrived, I spent two and a half hours with Lisa Cron trying to answer a question that had stalled my book: what is story, really, and why does it have such a grip on us?

I was stuck. So I went looking for people who understood #storytelling better than I did. Lisa was the first.

She wrote Wired for Story and Story or Die, worked as a literary agent and Hollywood story analyst, and has taught at UCLA since 2006. I expected craft advice. I got biology.

Her claim that the brain uses story as a kind of virtual reality simulator stayed with me long after we stopped recording. If that’s true, what happens when machines can produce stories endlessly, cheaply, and tuned to each of us? Whoever writes the story ends up shaping the simulation.

We also got into why more evidence can push people further away, the one real way to step into someone else’s shoes, the cure and the poison of story, and whether social media had already hacked our narrative wiring before #AI showed up to scale it.

I asked these questions in 2022. They read differently in 2026.

The end of aging could be closer than we think | Aubrey de Grey

â–ș Guest · Aubrey de Grey: / aubrey-de-grey-24260b.

In today’s episode, we have the pleasure of speaking with Aubrey de Grey, a biomedical gerontologist and longevity pioneer with a PhD in Biology from Cambridge. We talk about longevity escape velocity, repairing the damage associated with aging, experiments combining rejuvenation treatments in mice, and the funding and public support needed to move longevity research forward and explore its potential benefits for human health. I hope you enjoy it.

â–ș Business inquiries.
Sponsorships, collaborations and partnerships: [email protected].
Talks and events: [email protected].

â–ș Subscribe and turn on notifications here: / @jonhernandezai.


▷ Timestamps:

Ploutos Browser

Forking: when AI models suddenly memorize too much.

AI models are expected to learn patterns from their training data and apply what they learn to new, unseen examples. But what happens when learning too much from repeated examples actually makes a model worse at handling unfamiliar ones? https://arxiv.org/abs/2610.00394v1

This paper explores a phenomenon called forking, discovered during NanoGPT autoresearch. The researchers found that when a model repeatedly trains on the same data, its performance on the training set can continue to improve while its performance on unseen validation data suddenly deteriorates. When plotted, the two loss curves split apart at certain training boundaries, resembling the branches of a fork.

The researchers investigated this behavior in a controlled NanoGPT setup and reproduced it in a DeepSeek-style model using a memory mechanism called Engram, which stores and retrieves patterns of word sequences. Their findings suggest that repeated training strengthens the model’s predictions for familiar sequences while making it less likely to predict alternative continuations it has not encountered. Rare contexts appear to contribute significantly to this problem.

Interestingly, the team also observed forking in certain short-training scenarios involving supervised fine-tuning and reinforcement learning-like methods. However, the effect was less pronounced when training budgets were larger or when the memory tables were more crowded.

Why does this matter? The discovery introduces another unexpected behavior in deep learning, alongside phenomena such as grokking and double descent. More importantly, it highlights a potential danger in AI-driven research automation: techniques that appear to improve model performance can introduce unintended problems that are easy to overlook.

The key takeaway: Better performance on training data does not always mean a better model. As AI agents increasingly automate machine learning experiments, their discoveries and proposed optimizations still need careful validation to ensure that apparent improvements translate into genuine generalization.

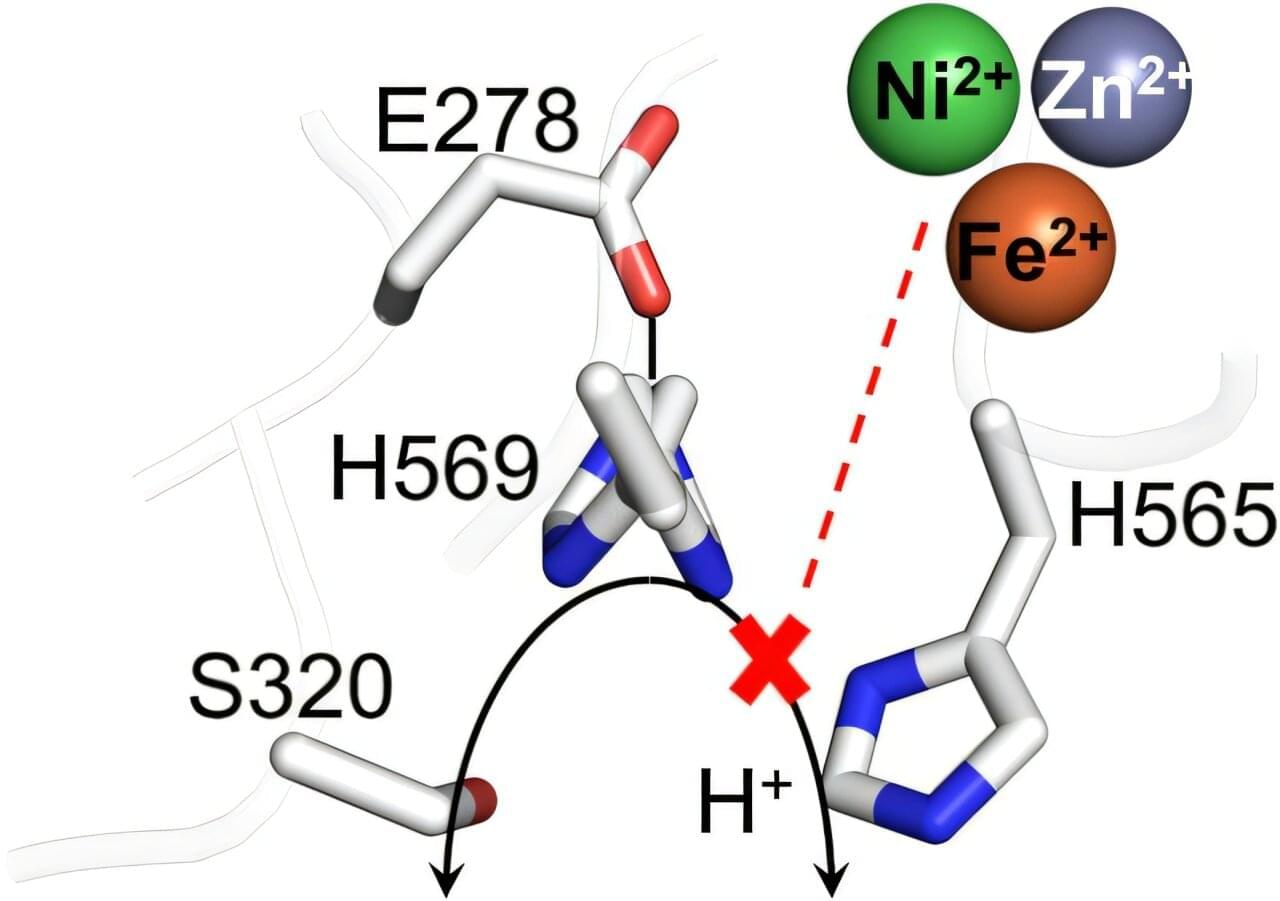
Molecular pendulum shuttles protons to enable rapid hydrogen production in enzymes

Nearly all metabolic processes require protons—positively charged hydrogen atoms. Although these are abundant in the cellular fluid, the biocatalysts involved depend on mechanisms for efficiently capturing protons and transporting them to the site where catalysis occurs. Enzymes from microorganisms can produce hydrogen (H₂) by combining electrons with protons. These so-called hydrogenases are so efficient that one biocatalyst can capture nearly 10,000 protons per second.

A team of researchers from the Photobiotechnology group at Ruhr University Bochum, Germany, has now discovered how they do this. The researchers reported their findings in the Journal of the American Chemical Society on Oct. 17, 2026.

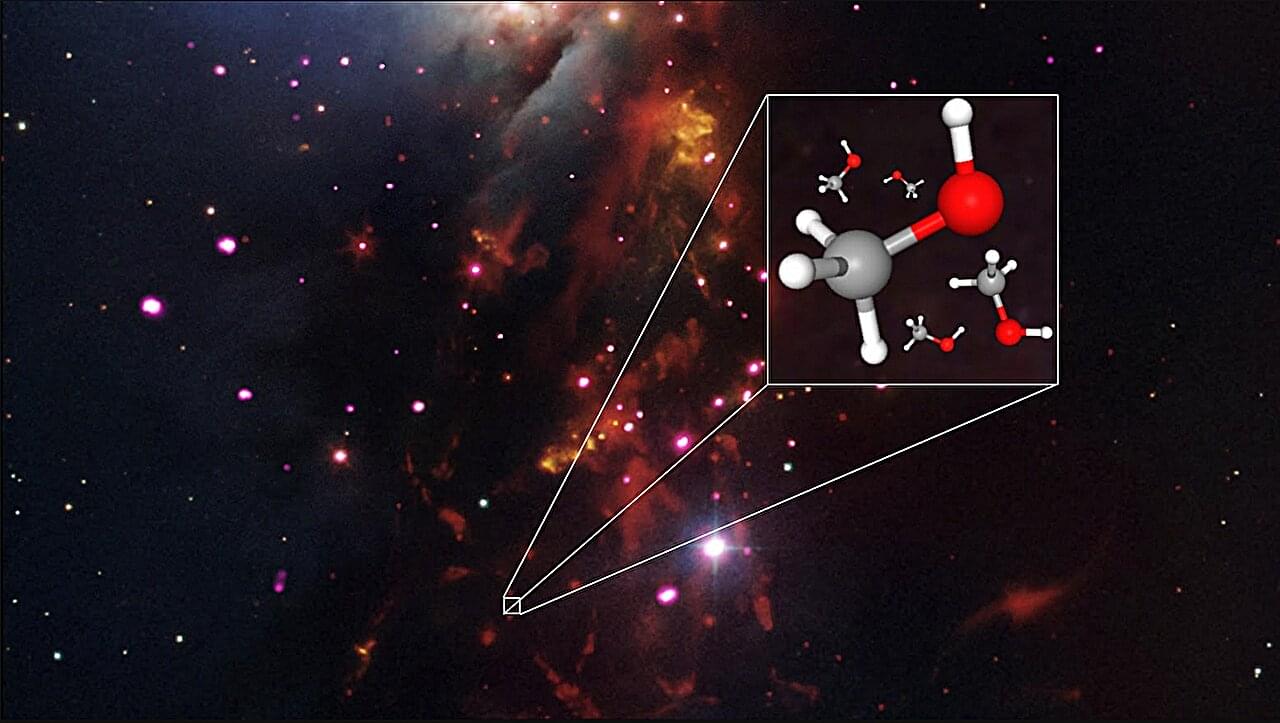
Alcohol in space: Exotic methanol discovered in planet-building zones

An international team of astronomers using the Atacama Large Millimeter/submillimeter Array (ALMA), of which the U.S. National Science Foundation National Radio Astronomy Observatory is a partner (NSF NRAO), has combined expertise from across the globe to open a new window on how the organic molecules that seed planets, and potentially life, form in space.

New results from the ALMA COMPASS Large Program (Complex Organic Molecules in Protostars with ALMA Spectral Surveys) show that young, still-forming stars are surrounded by a surprisingly sophisticated “chemical starter kit,” including organic molecules such as methanol that may one day enrich planets.

“We are getting completely new insights into the complex chemistry occurring around the youngest protostars,” said Jes Jþrgensen, professor at the Niels Bohr Institute of the University of Copenhagen and principal investigator of the program. “The interesting question is how these chemical ingredients may influence the conditions on planets and potentially the origin of life there.”

A suite of engineered mice for interrogating psychedelic drug actions

This national research on lsd and ultra lsd called large scale docking where a digital cell is used and then automatically new compounds and discoveries can be made by the millions to find the right amount of scaffolding for the compounds to work in a non hallucinogenic way to essentially even work with schizophrenia patients but his work is not done yet as it is a very complex process.


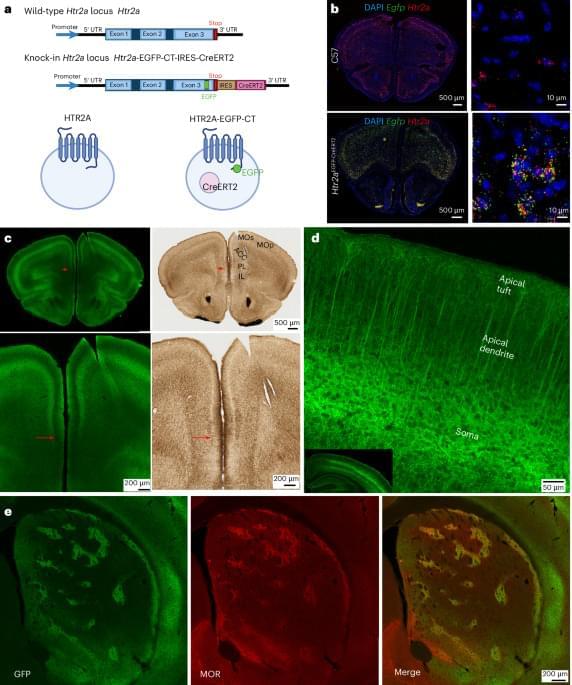
Chiu et al. have developed engineered HTR2A mouse lines enabling in vivo mapping, targeting and modulation of receptor-expressing neurons and validated their utility across biochemical, electrophysiological and behavioral studies of psychedelic mechanisms.