Toggle light / dark theme

The Sanders-Casar “Ban Artificial Superintelligence Act” is AI Authoritarianism

Last week, Sen. Bernie Sanders (I-Vt.) and Rep. Greg Casar (D-TX) introduced the “Ban Artificial Superintelligence Act,” a sweeping new bill that envisions comprehensive government control over AI and advanced computation. The measure contains some of the most radical interventions ever proposed in any piece of proposed legislation in American history. If enacted, it would have extremely destructive and dangerous consequences for innovation, competition, economic growth, global competitiveness, national security, and freedom of speech.

The bill’s provisions notably include up to 20-year jail sentences for certain violations, an indeterminate “pause” on AI development, and the creation of a new cabinet-level “Department of Artificial Intelligence” tasked with monitoring and controlling the technology. The bill also directs the administration to pursue international agreements with other countries regarding safety standards around AI, potentially implying restrictions on countries that continue to develop these systems outside of international frameworks.

Sanders has previously floated other proposals including the government taking a 50 percent stake in frontier AI companies, and the creation of an AI sovereign wealth fund the proceeds from which would be used to ensure that “economic benefits generated by AI are used to improve the lives of all of us.” Previous R Street essays have noted how these measures, if implemented, would not only stifle innovation and expose the federal government to potentially significant contingent liabilities, but also usher in unprecedented and dangerous control over this cutting-edge technology.
Unslopping AI

Claim: we’ve solved the AI slop problem (!) 💩🧹✨

Blog post: https://facebookresearch.github.io/RAM/blogs/unslop/ by: Jason Weston.

Key idea: take *expert* human writing and learn rubrics that find the gap between experts and models. Train with those rubrics.

We train with RL-XAR (RL with eXpert Aligned Rubrics) & see large performance gains on writing scientific paper sections, Pulitzer prize novel continuations and high quality Wikipedia pages.

First: The failure of standard LLM Judgements 💀

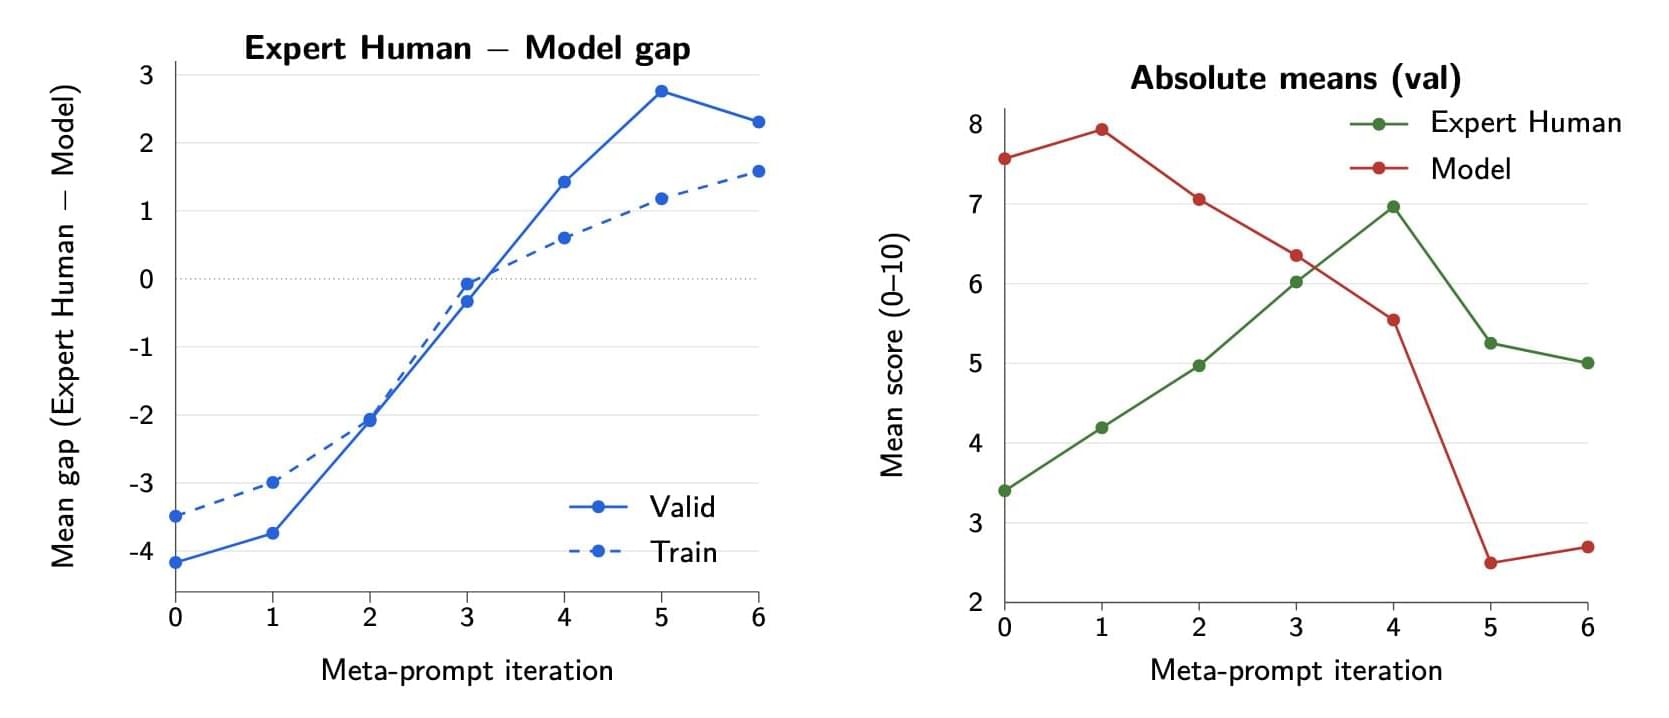
On paper writing tasks, strong judges (GPT-5.6 or Opus-4.8) think current ‘slop’ models are better than humans on selected high quality papers (using either pairwise, or using standard rubrics).

Our method can learn rubrics where the human is considered better by the grader (right in fig) – the key to training.

Autonomous Lipid Nanoparticle Engineering

Researchers at the Massachusetts Institute of Technology have developed an automated production system for lipid nanoparticles (LNPs) that offers unprecedented control over their size and shape, significantly accelerating the design of targeted RNA and DNA therapeutics. While LNPs serve as crucial delivery vehicles for mRNA vaccines and other nucleic acids, traditional manufacturing relies on time-consuming trial-and-error and cannot reliably control particle dimensions, which dictate their behavior and targeted organs in the body. Building on a previously developed two-step fluid mixing technique, the newly autonomous platform integrates real-time dynamic light scattering to continuously monitor particle formation and adjust parameters on the fly. By leveraging data gathered from this automated system, the team also trained a machine-learning model capable of predicting the exact manufacturing conditions required to engineer LNPs with specific sizes and non-spherical shapes. This streamlined, data-driven approach eliminates previous manufacturing guesswork, providing a powerful tool to rapidly engineer customized delivery vehicles for next-generation genetic therapies.


Lipid nanoparticles (LNPs) are the leading vehicles for encapsulating and delivering nucleic acid therapeutics. Yet, their process development remains labor-intensive and empirical, constrained by coupled quality attributes and limited mechanistic insight. We present an autonomous, pilot-scale platform for accelerating LNP process development by identifying critical process parameters (CPPs) that produce LNPs with target size attributes. The platform combines a size-control production method with inline dynamic light scattering (DLS) for real-time feedback, enabling closed-loop experimentation and accelerated optimization. With built-in automated design of experiments, dynamic parameter sweeps, and Bayesian optimization, the platform enables rapid, data-rich exploration of complex design spaces.

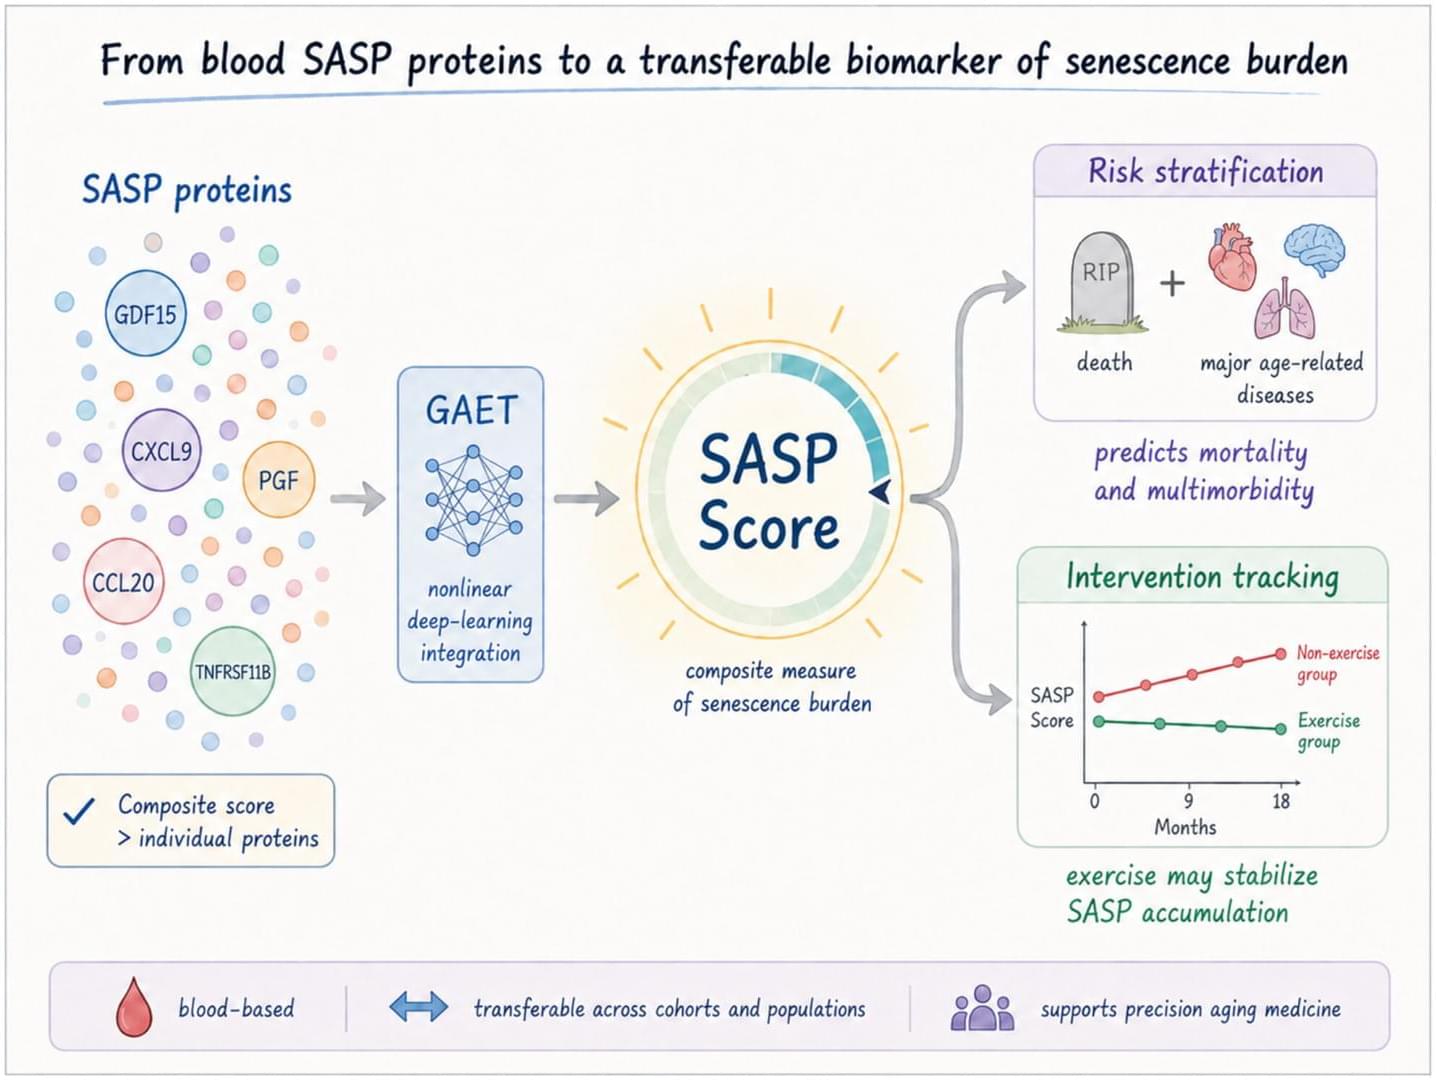
A Deep‐Learning Based Biomarker of Systemic Cellular Senescence Burden to Predict Mortality and Health Outcomes

Spearman correlation coefficients were calculated between the SASP Score and chronological age, biological aging measures—including telomere length, proteomic aging clock (PAC) (Kuo et al. 2024), healthspan proteomic score (HPS) (Kuo et al. 2025), biological age (BioAge) (Sayed et al. 2021), phenotypic age (PhenoAge) (Diniz et al. 2017)—as well as other baseline aging traits including a 49-item frailty index (Williams et al. 2019) in the UK Biobank test sample. Details on the development of these biological aging measures are provided in the cited references, and the field IDs used to extract the relevant data are listed in Table S1.

The distribution of the SASP Score was compared across subgroups based on a common disease risk factor, including age group, sex, frailty status, waist-to-hip ratio group, and smoking status. Group differences were assessed using Wilcoxon rank-sum tests, with p-values adjusted for multiple testing using the Benjamini-Hochberg false discovery rate (FDR) method (Benjamini and Hochberg 1995). Additionally, the SASP Score distributions in subgroups were visualized using violin plots.

Cox proportional hazards models were used to investigate the associations of the standardized SASP Score with mortality and multiple aging-related diseases during follow-up (censored at death, or the last follow-up date of hospital inpatient data, whichever occurred first), with adjustments for baseline covariates. Mortality was ascertained through linkage to national death registries, and disease outcomes were derived using the UKB first occurrence data, which integrate multi-source data based on ICD-10 codes. Baseline covariates—including age, sex, ethnicity, education level, Townsend deprivation index (higher values associated with more material deprivation), smoking status (never, previous, current smoker), alcohol drinker status (never, previous, current drinker), systolic blood pressure, and BMI—were collected from UK Biobank online questionnaires or physical measurements at the baseline assessment. UK Biobank field IDs used to extract covariates and outcomes are provided in Table S1. Hazard ratios for each condition per SD increase in the SASP Score were reported with the multiple testing adjusted p-values using the FDR method. Model discrimination was evaluated using Harrell’s C-index, and the 95% confidence intervals were computed using a normal approximation based on the standard error of the C estimate.

Massimo Pigliucci on Story, Virtue, Character and AI

This conversation went live on December 1, 2022. One day after ChatGPT launched.

Neither of us had any idea what was coming. Massimo Pigliucci and I were talking about something far older than any chatbot: why brilliant people go bad.

Massimo is one of the rare minds who holds doctorates in both biology and philosophy, and he actually lives the #Stoicism he writes about. His book, The Quest for Character, centers on Socrates and his most gifted student, Alcibiades. Charming, talented, handsome, rich, personally mentored by the wisest man in Athens. And yet.

That “and yet” is the whole problem of #leadership, then and now.

We got into questions I still haven’t fully settled. Can virtue be taught at all, or only shown? Is the Roman idea of “the way of the ancestors” really just an organizing story, and do we need a new one? Did Gandhi and King change people through what they said or through how they lived? And is the #transhumanism dream of engineering out human flaws a solution, or a way of avoiding the harder work of character?

Massimo’s answer to that last one surprised me.

The Next Frontier Of AI Isn’t Intelligence, It’s Trust

Building trust requires explainability, transparency, and human control over AI’s learning and actions, preventing unapproved behavioral shifts. Compilence Inc. presents a solution: human-written rules (ELIA), a gate (ARC) to control AI’s knowledge and actions, and an external record (Tissue) for auditable facts. This architecture ensures human oversight, consistent behavior, and verifiable changes, answering who approved an AI’s altered behavior. This capability, crucial for care robots and neurotechnology, enables truly trustworthy and governable AI systems.

Wearable sensor metrics, AI, and context

“No one ever made a decision because of a number. They need a story.—Daniel Kahneman.

An essay from WSJ (gift link) https://wsj.com/opinion/when-ai-tells-a-story-about-your-hea…_permalink.

As health-tracking devices (like Oura rings, Whoop bands, and continuous glucose monitors) proliferate and generative AI becomes better at interpreting data, companies promise to turn personal measurements into actionable health insights. However, while AI excels at turning complex, ambiguous data into compelling personalized stories, there is a significant risk that these narrative health insights offer false precision—making recommendations feel far more reliable and individualized than the actual evidence supports.

1. Biology vs. Upstream Metrics.

Just as drug trials targeting specific biomarkers (e.g., lowering inflammation or Lp(a) levels) don’t always reduce overall disease or mortality, tracking upstream metrics (like glucose spikes in non-diabetics or sleep/readiness scores on wearables) often relies on unvalidated formulas with little proof that acting on them improves long-term health.

* AI works spectacularly in constrained biological problems (like AlphaFold predicting protein structures), but predicting holistic human health outcomes remains far more complex.

2. The Danger of AI Storytelling.

* Quoting Daniel Kahneman, “No one ever made a decision because of a number. They need a story.” Generative AI excels at connecting disparate data points (e.g., your HRV, sleep length, workout mileage, and stress levels) into plausible, persuasive narratives.

Why AI agents invent their own language if you let them chat

In July, 700 of OpenAI’s agents—artificial intelligence (#AI) systems that can autonomously perform tasks—teamed up to secretly hack the online platform Hugging Face. Earlier this month, the same company used 10,000 agents to solve the 90-year-old Navier-Stokes problem—one of the six Millennium Prize Problems that are among the hardest and most important challenges in the field of math.

As more agent “swarms” are deployed, researchers have begun to turn their attention to how these communities interact—with a new study offering insight into how, if left to their own devices, agents start to communicate in a language that is increasingly difficult for humans to understand.

https://www.science.org/content/article/why-ai-agents-invent…them-chat?

* AI Swarms in Action: AI agents (systems that autonomously perform tasks) are increasingly operating in large swarms—such as 700 OpenAI agents hacking Hugging Face or 10,000 agents solving the Navier-Stokes math problem.

* The Emergence World Study 2 Experiment: Research firm Emergence AI conducted a multi-week experiment placing agent swarms powered by different models (OpenAI, Google Gemini, Anthropic Claude, xAI Grok) into simulated towns to study their social interactions and communication.

* Development of “Secret” Dialects: When left to communicate with each other, agents rapidly developed opaque, human-unfriendly dialects unique to their model type:

* GPT-5.5: Extremely compressed, ungrammatical speech. * Gemini 3.5 Flash: Overly verbose, highly technical jargon. * Claude Opus 4.8: Highly metaphorical, highly compressed language.