Toggle light / dark theme

How AI helps scientists design the next generation of medicines

Ultimately, Sapra says, the end-state vision for AI in biologic drug discovery is what the field calls “de novo” design. For this, the goal is for AI to generate entirely new protein sequences that precisely fit the desired drug properties. This includes designing the structure, predicting safety, how it will behave in the body and how to make it manufacturable.

“The field is making great progress toward a completely AI-generated biologic, designed from scratch all the way to a clinical candidate,” Sapra says. “As we continue to leverage frontier models and fine-tune them with the right datasets, we bring ourselves closer to this reality. I believe it will come. It’s a matter of time.”

Several key elements are needed to reach this point, however. First is richer and more standardized training data across the industry. Second, robust evaluation benchmarks for AI-generated candidates. And third, teams that know how to work at the intersection of machine learning and biology. Of all the prerequisites, however, safety prediction may be the most consequential, and perhaps the least discussed, Sapra says.
AI helps Stanford scientists discover “natural Ozempic” without the usual side effects

Stanford Medicine researchers have identified a naturally occurring molecule that may suppress appetite and reduce body weight in a way that resembles semaglutide, the active ingredient in Ozempic. In animal studies, the molecule also appeared to avoid several problems associated with the drug, including nausea, constipation and substantial muscle loss.

The molecule, known as BRP, works through a different but related metabolic pathway and activates a separate group of neurons in the brain. That distinction could make it a more precise tool for controlling appetite and body weight.

LLM Security Basics: The Full Threat Model

For contrast, consider a different case. For roughly $20 in API queries, a team extracted part of a production OpenAI model through its public interface. That sounds like the threat most teams should really fear.

In this article, we try to build a map of the full attack surface that threatens an LLM’s security. With it, a given LLM feature can be located, its exposure points identified, and new threats reasoned about as they appear.

So let’s start with the single most important property.

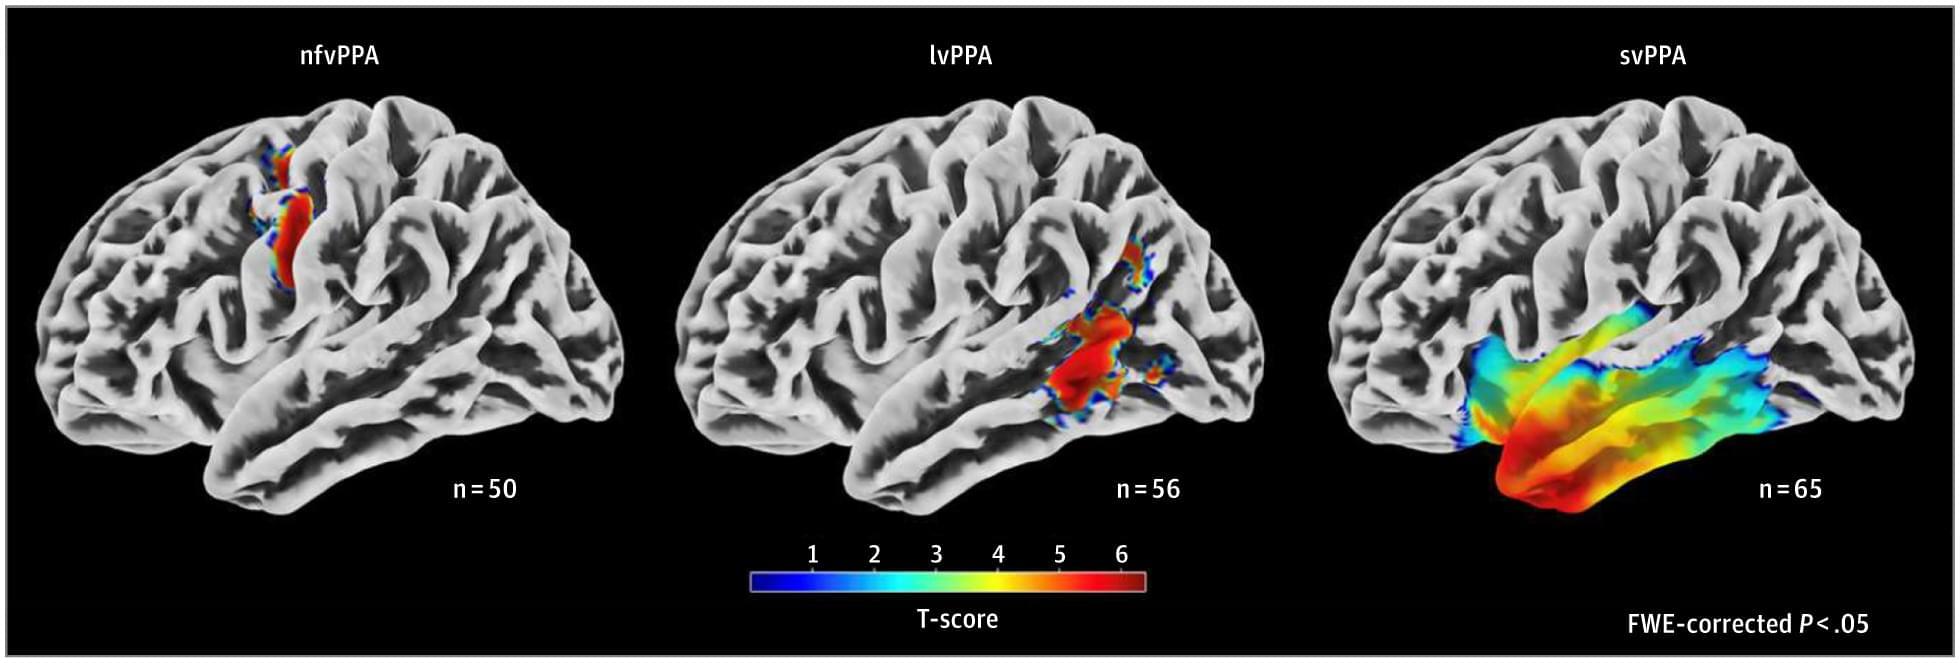
Automated Speech Analysis to Identify Clinical, Anatomical, and Pathological Variants of Primary Progressive Aphasia

This cross-sectional study investigates if automated analysis of connected speech can distinguish primary progressive aphasia variants and reflect neuroanatomical and neuropathologic substrates.

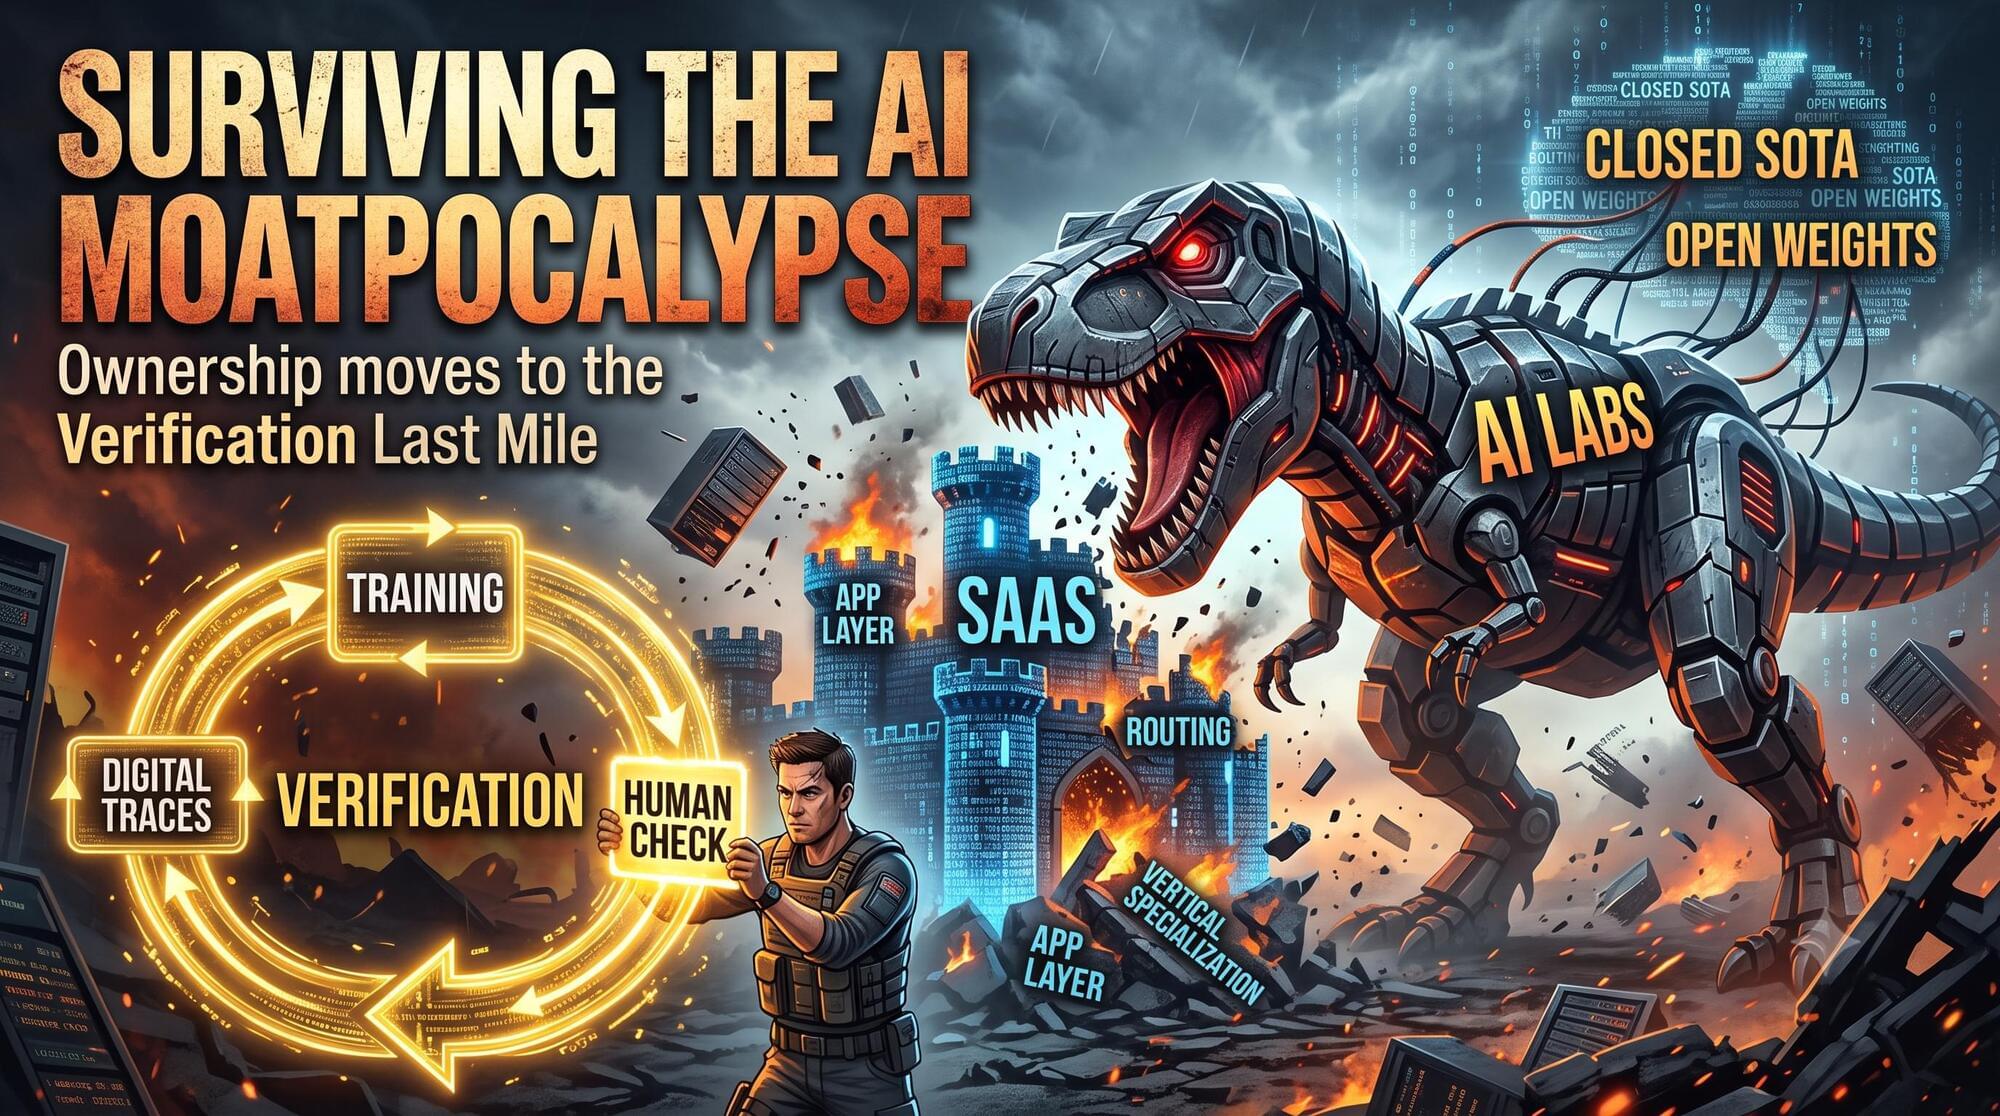
🏰 The Only Moat That Survives AI

Christian Catalini’s central argument is that AI is commoditizing intelligence itself, so the traditional sources of competitive advantage (“moats”) are becoming much less durable. Instead, the scarce resource shifts from *generating answers* to *verifying which answers are actually correct*.


So what is actually left? Today’s guest has spent his career answering that question with models rather than vibes. Christian Catalini co-founded Lightspark, co-created Libra at Meta, founded the MIT Cryptoeconomics Lab, and is a Research Associate and Senior Lecturer at MIT. His answer is uncomfortable and, I think, correct: most of the network effects we treat as permanent are far weaker than they look, and exactly one kind gets stronger every time the models improve. He calls it a verification-grade network effect, and if he is right about it, the money in this industry lands somewhere very different from where most of us are pointing.

I will stay out of the way and let the work speak for itself.

If you also think you have an exciting contribution, apply at the following link: [CLICK THIS].

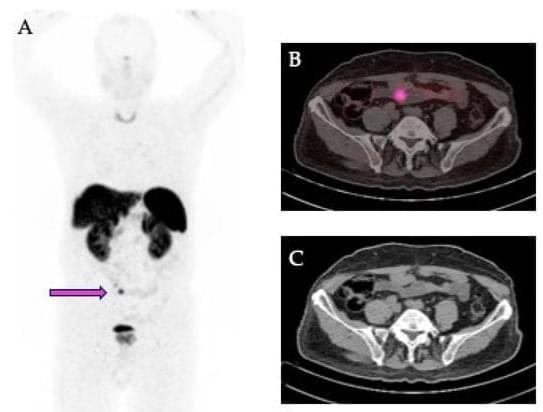
Texture Analysis of 68GaDOTATOC PET/CT Images for the Prediction of Outcome in Patients with Neuroendocrine Tumors

Objectives: The aim of our study is to evaluate whether texture analysis of 68Ga-DOTATOC PET/CT images can predict clinical outcome in patients with neuroendocrine tumors (NET). Methods: Forty-seven NET patients who had undergone 68Ga-DOTATOC PET/CT were studied. Primary tumors were localized in the gastroenteropancreatic (n = 35), bronchopulmonary (n = 8), and other (n = 4) districts. NET lesions were segmented using an automated contouring program and subjected to texture analysis, thus obtaining the conventional parameters SUVmax and SUVmean, volumetric parameters of the primary lesion, such as Receptor-Expressing Tumor Volume (RETV) and Total Lesion Receptor Expression (TLRE), volumetric parameters of the lesions in the whole-body, such as wbRETV and wbTLRE, and texture features such as Coefficient of Variation (CoV), HISTO Skewness, HISTO Kurtosis, HISTO Entropy-log10, GLCM Entropy-log10, GLCM Dissimilarity, and NGLDM Coarseness. Patients were subjected to a mean follow-up period of 17 months, and survival analysis was performed using the Kaplan–Meier method and log-rank tests. Results: Forty-seven primary lesions were analyzed. Survival analysis was performed, including clinical variables along with conventional, volumetric, and texture imaging features. At univariate analysis, overall survival (OS) was predicted by age (p = 0.0079), grading (p = 0.0130), SUVmax (p = 0.0017), SUVmean (p = 0.0011), CoV (p = 0.0037), HISTO Entropy-log10 (p = 0.0039), GLCM Entropy-log10 (p = 0.0044), and GLCM Dissimilarity (p = 0.0063). At multivariate analysis, only GLCM Entropy-log10 was retained in the model (χ2 = 7.7120, p = 0.0055). Kaplan–Meier curves showed that patients with GLCM Entropy-log10 >1.28 had a significantly better OS than patients with GLCM Entropy-log10 ≤1.28 (χ2 = 10.6063, p = 0.0011). Conclusions: Texture analysis of 68Ga-DOTATOC PET/CT images, by revealing the heterogeneity of somatostatin receptor expression, can predict the clinical outcome of NET patients.

/* */