Light is renowned for its incredible speed.
Category: futurism – Page 449
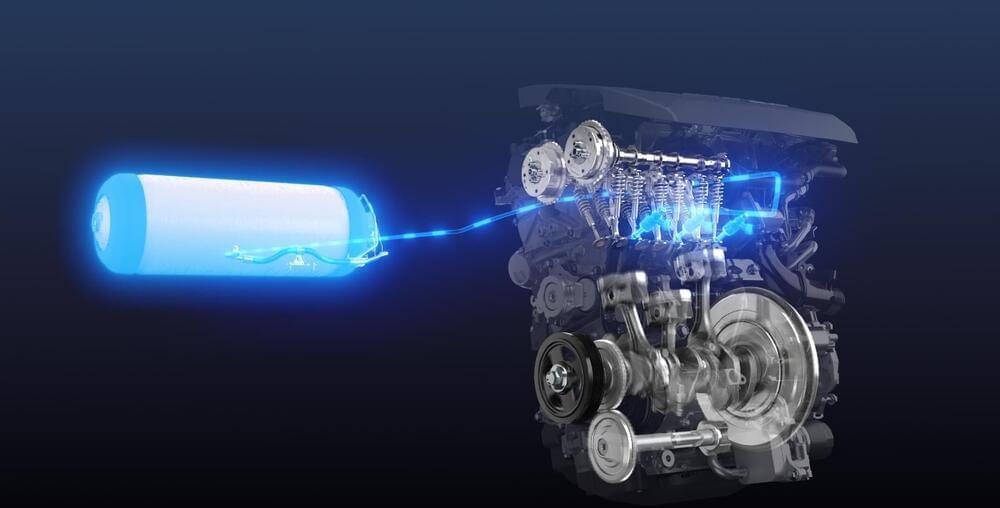
This brand presents the first water engine: 2500 ºC and dual injection to outperform hydrogen
This brand has presented the first water engine in history: 2,500 ºC and the end of hydrogen (and Tesla, of course)
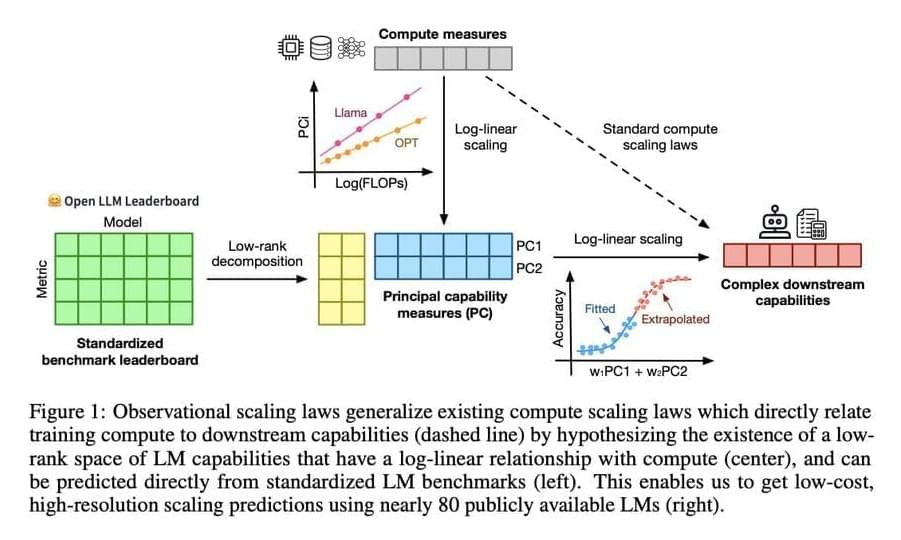
This Machine Learning Paper from Stanford and the University of Toronto Proposes Observational Scaling Laws: Highlighting the Surprising Predictability of Complex Scaling Phenomena
Language models (LMs) are a cornerstone of artificial intelligence research, focusing on the ability to understand and generate human language. Researchers aim to enhance these models to perform various complex tasks, including natural language processing, translation, and creative writing. This field examines how LMs learn, adapt, and scale their capabilities with increasing computational resources. Understanding these scaling behaviors is essential for predicting future capabilities and optimizing the resources required for training and deploying these models.
The primary challenge in language model research is understanding how model performance scales with the amount of computational power and data used during training. This scaling is crucial for predicting future capabilities and optimizing resource use. Traditional methods require extensive training across multiple scales, which is computationally expensive and time-consuming. This creates a significant barrier for many researchers and engineers who need to understand these relationships to improve model development and application.
Existing research includes various frameworks and models for understanding language model performance. Notable among these are compute scaling laws, which analyze the relationship between computational resources and model capabilities. Tools like the Open LLM Leaderboard, LM Eval Harness, and benchmarks like MMLU, ARC-C, and HellaSwag are commonly used. Moreover, models such as LLaMA, GPT-Neo, and BLOOM provide diverse examples of how scaling laws can be practiced. These frameworks and benchmarks help researchers evaluate and optimize language model performance across different computational scales and tasks.
Isaac Newton predicted when the world is going to end and we haven’t got long left
Link :
In 1,704, Sir Isaac Newton predicted the year that the world was going to come to an end, however it’s not the apocalypse you’re probably thinking of.
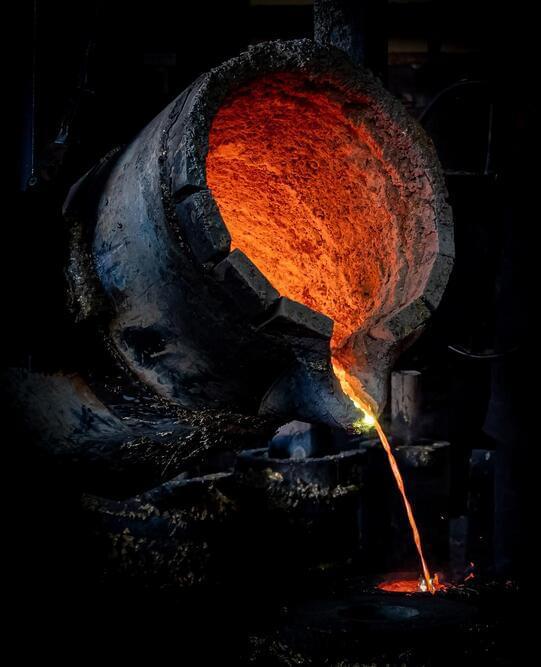
MIT scientists discovered how to make steel with electricity
Scientists at MIT found a way to create electric steelmaking, allowing them to create steel using electricity instead of coal.
Study Finds That 52 Percent of ChatGPT Answers to Programming Questions Are Wrong
78 percent of the answers suffer from different degrees of inconsistency to human answers.
Researchers found that 52 percent of answers to programming questions generated by ChatGPT were incorrect.
Thyroid Hormones (FT4, FT3): What’s Optimal?
Join us on Patreon! https://www.patreon.com/MichaelLustgartenPhDDiscount Links: NAD+ Quantification: https://www.jinfiniti.com/intracellular-nad-test/Use Cod…
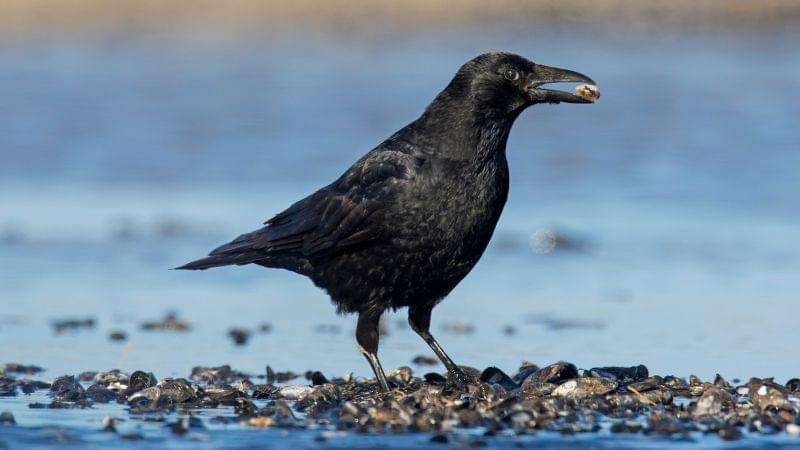
Crows can count much in the same way as human toddlers, study finds
Crows can vocally count up to four. The intelligent birds recognize and react to numbers in a process similar to that of human cognition, according to a new study.
The Guy Who Made Chaotic Desktop Goose Turned Notepad into MS Paint
You can actually play his upcoming shooter in the app.