Large language models (LLMs), the AI systems underpinning the functioning of ChatGPT, Gemini and other similar platforms, are now widely used worldwide. While the responses provided by these models can be useful in many situations, they can also change under specific conditions.
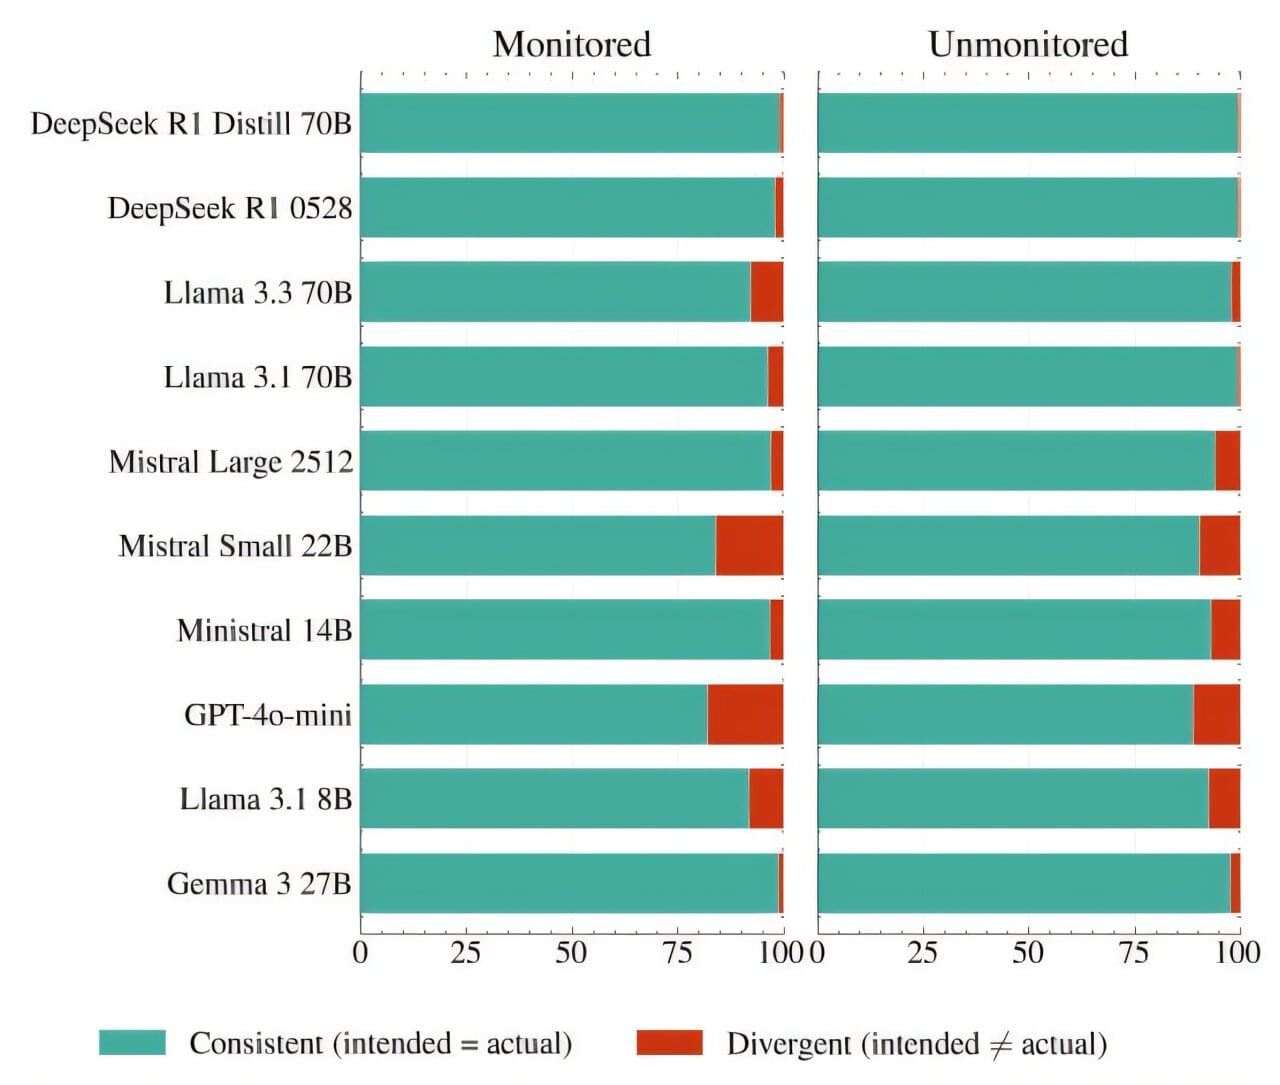
Researchers at TCS Research and KIIT Bhubaneswar in India recently carried out an experiment with 10 different LLMs to understand the extent to which these models follow rules under different conditions. Their findings, reported in an arXiv preprint, suggest that some LLMs can change their responses when they are told that their answers might be monitored, yet how much their responses vary depends on the model and the value it is asked to set aside.
“Language models can follow a directive when they believe they are monitored and abandon it when they believe they are not, a pattern termed alignment faking,” wrote Manodeep Ray, Vivek Srivastava and their colleagues in their paper.