Toggle light / dark theme

Get the latest international news and world events from around the world.

Log in for authorized contributors

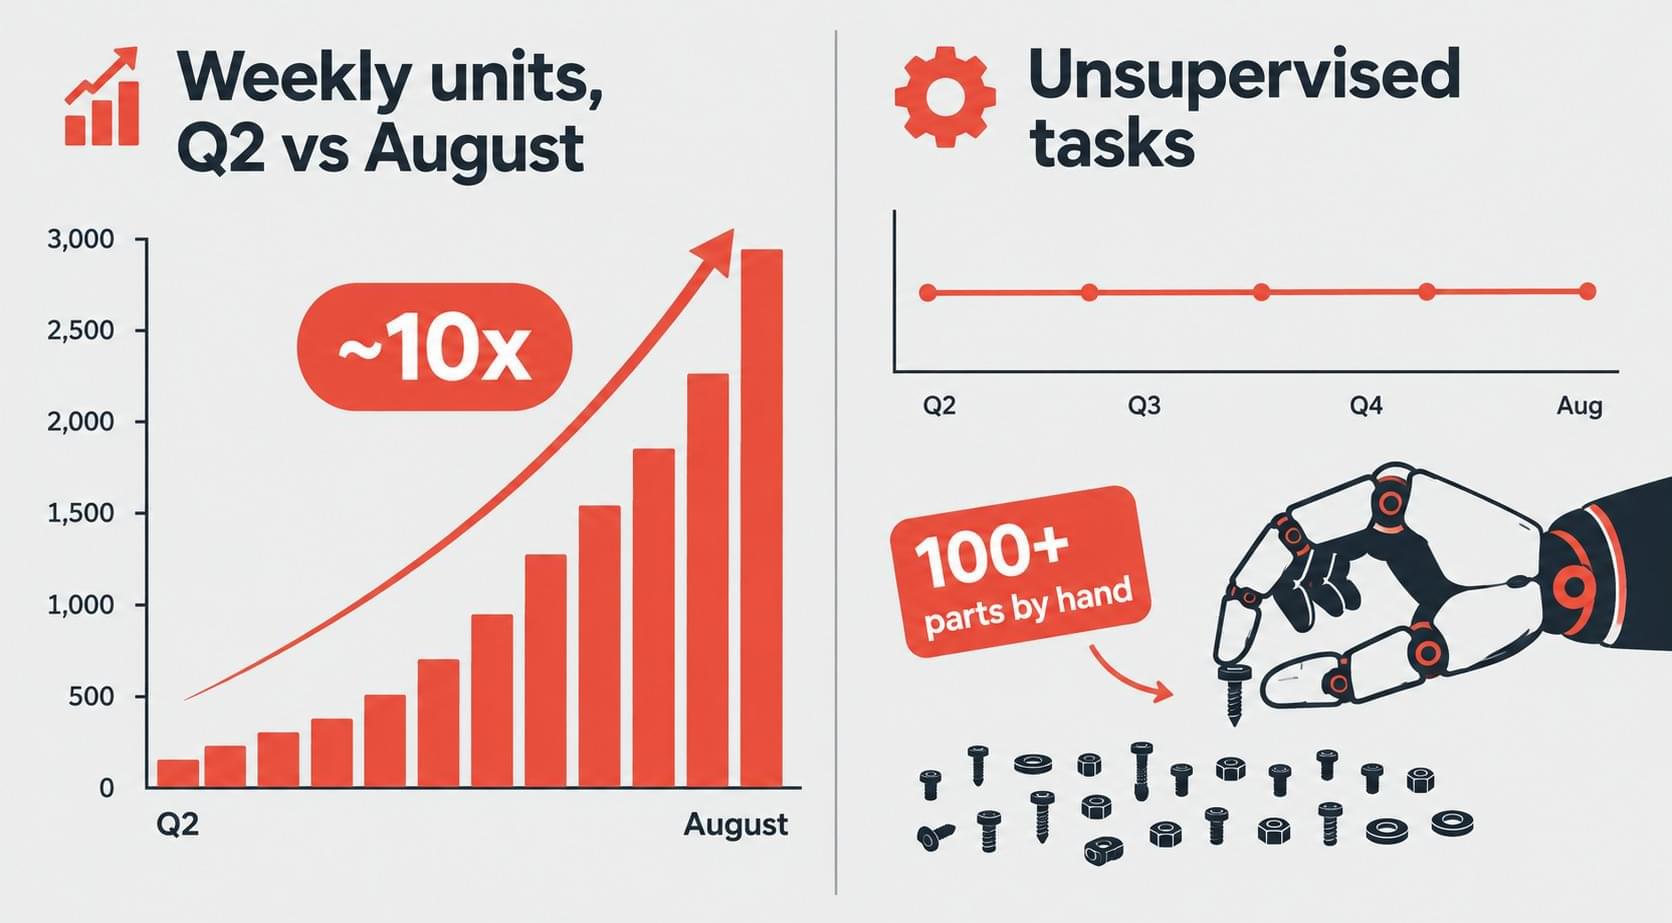
Industrial AI Pilot Revenue Hides A Widening Production Gap

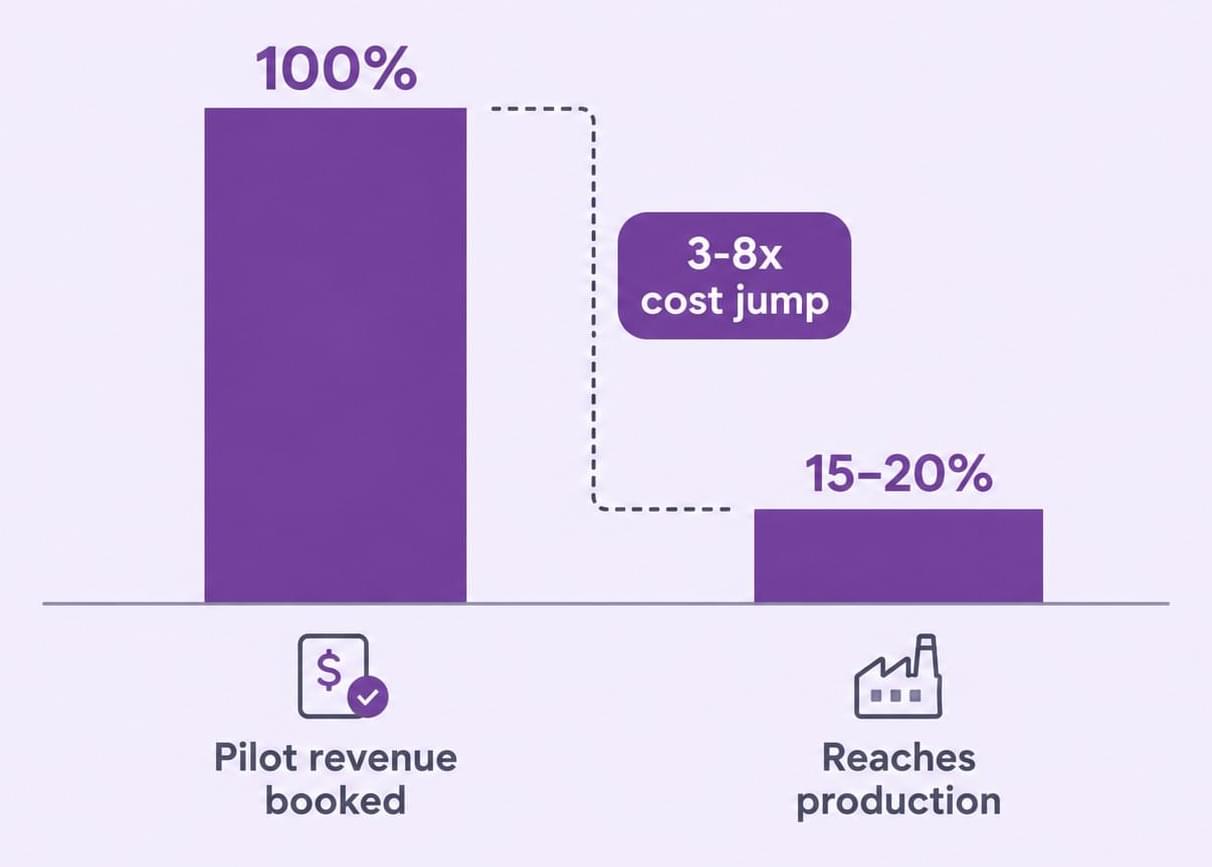
Most industrial AI pilots are booked as if they are the start of a multi-year platform deal. In reality, most never become one.

RAND and MIT’s 2026 analysis puts the failure rate at 80.3%. Multiple studies converge on 70–88% of AI pilots never reaching production.

The bigger financial risk is the scale-up cost. Moving a successful pilot into production typically costs 250–400% more than the pilot itself. A $100,000 pilot can need $300,000–$800,000 more to go live.

Most buyers do not reserve that budget going in. When the real number appears after the fact, the project dies for lack of an approved line item — not for lack of results.

Vendors whose revenue holds up past year one tend to price the pilot and the scale-up as separate milestones, and tie part of the scale fee to actual production usage.

Pilot bookings are not a leading indicator of platform revenue. Production conversion is.

Full analysis:

The Sanders-Casar “Ban Artificial Superintelligence Act” is AI Authoritarianism

Last week, Sen. Bernie Sanders (I-Vt.) and Rep. Greg Casar (D-TX) introduced the “Ban Artificial Superintelligence Act,” a sweeping new bill that envisions comprehensive government control over AI and advanced computation. The measure contains some of the most radical interventions ever proposed in any piece of proposed legislation in American history. If enacted, it would have extremely destructive and dangerous consequences for innovation, competition, economic growth, global competitiveness, national security, and freedom of speech.

The bill’s provisions notably include up to 20-year jail sentences for certain violations, an indeterminate “pause” on AI development, and the creation of a new cabinet-level “Department of Artificial Intelligence” tasked with monitoring and controlling the technology. The bill also directs the administration to pursue international agreements with other countries regarding safety standards around AI, potentially implying restrictions on countries that continue to develop these systems outside of international frameworks.

Sanders has previously floated other proposals including the government taking a 50 percent stake in frontier AI companies, and the creation of an AI sovereign wealth fund the proceeds from which would be used to ensure that “economic benefits generated by AI are used to improve the lives of all of us.” Previous R Street essays have noted how these measures, if implemented, would not only stifle innovation and expose the federal government to potentially significant contingent liabilities, but also usher in unprecedented and dangerous control over this cutting-edge technology.

Unslopping AI

Claim: we’ve solved the AI slop problem (!) 💩🧹✨

Blog post: https://facebookresearch.github.io/RAM/blogs/unslop/ by: Jason Weston.

Key idea: take *expert* human writing and learn rubrics that find the gap between experts and models. Train with those rubrics.

We train with RL-XAR (RL with eXpert Aligned Rubrics) & see large performance gains on writing scientific paper sections, Pulitzer prize novel continuations and high quality Wikipedia pages.

First: The failure of standard LLM Judgements 💀

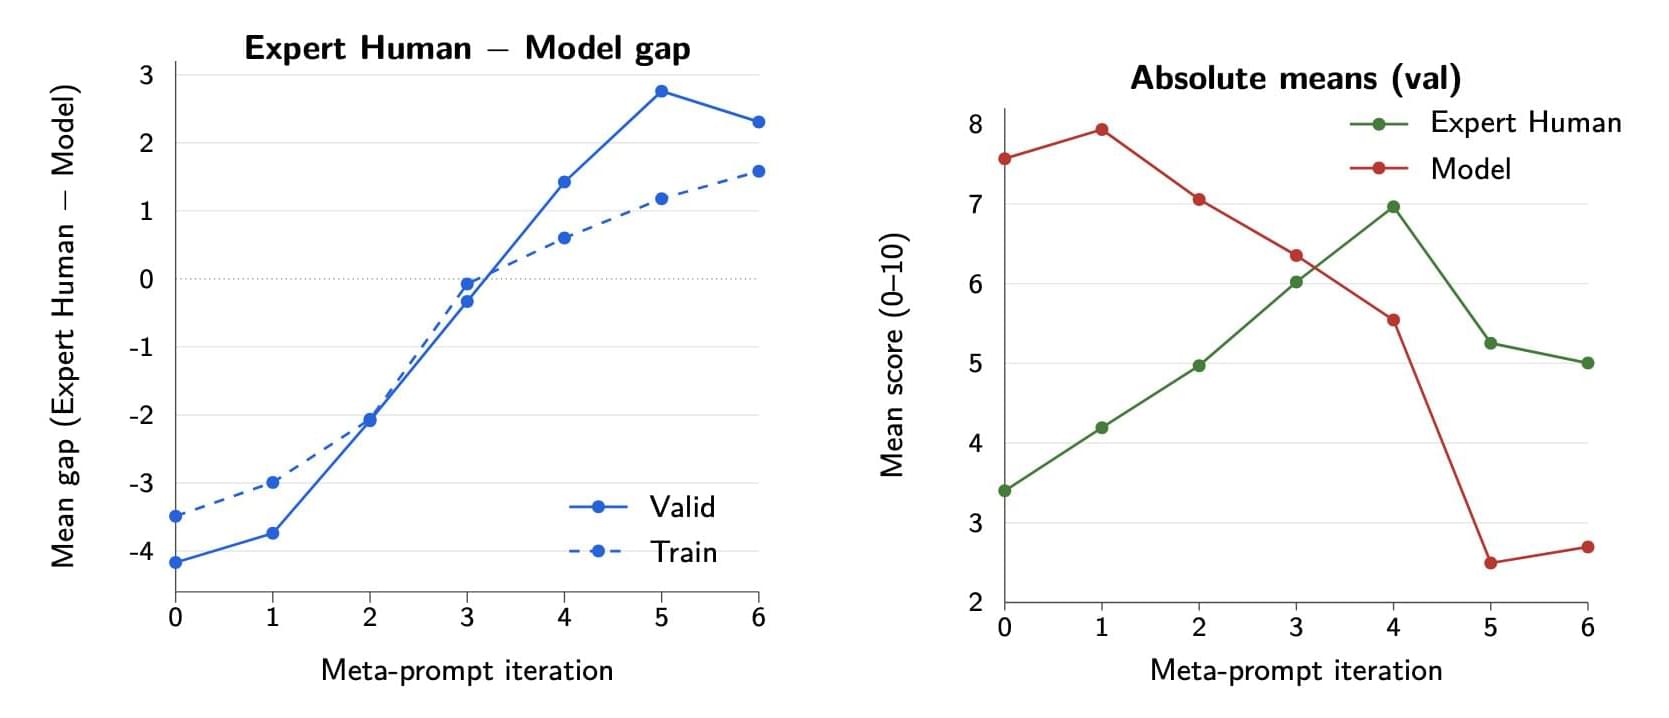
On paper writing tasks, strong judges (GPT-5.6 or Opus-4.8) think current ‘slop’ models are better than humans on selected high quality papers (using either pairwise, or using standard rubrics).

Our method can learn rubrics where the human is considered better by the grader (right in fig) – the key to training.

Autonomous Lipid Nanoparticle Engineering

Researchers at the Massachusetts Institute of Technology have developed an automated production system for lipid nanoparticles (LNPs) that offers unprecedented control over their size and shape, significantly accelerating the design of targeted RNA and DNA therapeutics. While LNPs serve as crucial delivery vehicles for mRNA vaccines and other nucleic acids, traditional manufacturing relies on time-consuming trial-and-error and cannot reliably control particle dimensions, which dictate their behavior and targeted organs in the body. Building on a previously developed two-step fluid mixing technique, the newly autonomous platform integrates real-time dynamic light scattering to continuously monitor particle formation and adjust parameters on the fly. By leveraging data gathered from this automated system, the team also trained a machine-learning model capable of predicting the exact manufacturing conditions required to engineer LNPs with specific sizes and non-spherical shapes. This streamlined, data-driven approach eliminates previous manufacturing guesswork, providing a powerful tool to rapidly engineer customized delivery vehicles for next-generation genetic therapies.


Lipid nanoparticles (LNPs) are the leading vehicles for encapsulating and delivering nucleic acid therapeutics. Yet, their process development remains labor-intensive and empirical, constrained by coupled quality attributes and limited mechanistic insight. We present an autonomous, pilot-scale platform for accelerating LNP process development by identifying critical process parameters (CPPs) that produce LNPs with target size attributes. The platform combines a size-control production method with inline dynamic light scattering (DLS) for real-time feedback, enabling closed-loop experimentation and accelerated optimization. With built-in automated design of experiments, dynamic parameter sweeps, and Bayesian optimization, the platform enables rapid, data-rich exploration of complex design spaces.

Researchers find how prostate tumors reshape the immune microenvironment

Researchers at The University of Texas MD Anderson Cancer Center have identified a previously unknown pathway that prostate tumors leverage to suppress the immune system by reshaping the tumor microenvironment to resist treatment. A combined targeted therapy approach improved antitumor responses and prolonged survival in preclinical models of castration-resistant prostate cancer.

The study, published in Cancer Discovery, was led by Di Zhao, Ph.D., associate professor of Experimental Radiation Oncology, and Nicholas Navin, Ph.D., chair of Systems Biology. The findings suggest that tumors use this pathway as a backup physical defense and may explain why therapies targeting the B7-H3 immune checkpoint may show limited efficacy when used alone.

Our study shows that the immune checkpoint B7-H3 does more than put the brakes on the immune system; it also reshapes the cells surrounding a tumor to help cancer grow and resist treatment. By uncovering how this process works, we identified a promising strategy that combines B7-H3-targeted therapy with MEK inhibition. These findings could help guide more effective, personalized treatments for patients whose tumors are unlikely to respond to B7-H3 therapy alone.

Tissue-specific aging clocks map structured aging-modulatory drug-score patterns across 49 human tissue and cell-line categories

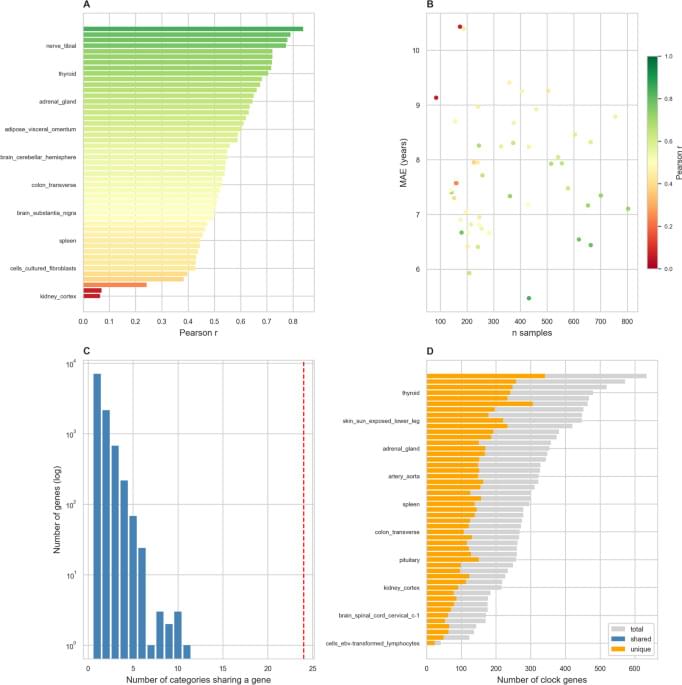
Aging clocks are typically trained on pooled multi-tissue data, implicitly assuming that aging is uniform across organs. Here we challenge this assumption by constructing 49 transcriptomic clocks across 47 tissue types and 2 cell-line categories from GTEx v8 (948 unique donors contributing to the retained clock categories) using donor-grouped cross-validation. Clocks achieved a median Pearson r of 0.543 (best: artery aorta, r = 0.855). We identified 10,253 unique clock genes, of which 69.2% appeared in only one tissue; however, null simulation confirmed that this low overlap is the expected consequence of sparse elastic-net selection rather than biological tissue-specificity. We then projected 3,926 LINCS L1000 compound-name entries onto each clock to build a drug × category age-reversal matrix. At a permissive threshold (|score|> 1.0), 94.2% of drugs showed mixed score directions (positive in some categories and negative in others). This permissive mixed-direction proportion was descriptive and did not itself exceed shuffled expectations. Under a more stringent exploratory criterion requiring |score|> 2.0 in at least three categories in each direction, 2.8% of compound entries showed pronounced bidirectional divergence, compared with approximately 0.1% under the shuffled null. Compound rankings remained stable when analysis was restricted to the 34 clocks with r ≥ 0.5 (Spearman ρ = 0.897 versus the full analysis). A Jaccard-based enrichment statistic yielded highly concordant compound rankings (median per-category Spearman ρ = 0.961), indicating that results were not artifacts of the enrichment method. After Benjamini–Hochberg FDR correction across all 192,374 drug-category pairs, only 0.79% reached FDR < 0.05, indicating that individual drug-category calls require caution. Rapamycin showed net pro-aging transcriptional signatures in our system; we explicitly emphasize that transcriptome-based scores and organismal lifespan are distinct endpoints. DepMap CRISPR analysis was repeated after GTEx-based standardization across 13 matched categories, although individual gene-level results were limited. Four statistical robustness tests confirmed model stability. These findings describe category-associated drug-score patterns and provide a tissue-aware resource for generating hypotheses about drug responses, while cautioning against over-interpretation of individual drug-category predictions without experimental validation.

A Deep‐Learning Based Biomarker of Systemic Cellular Senescence Burden to Predict Mortality and Health Outcomes

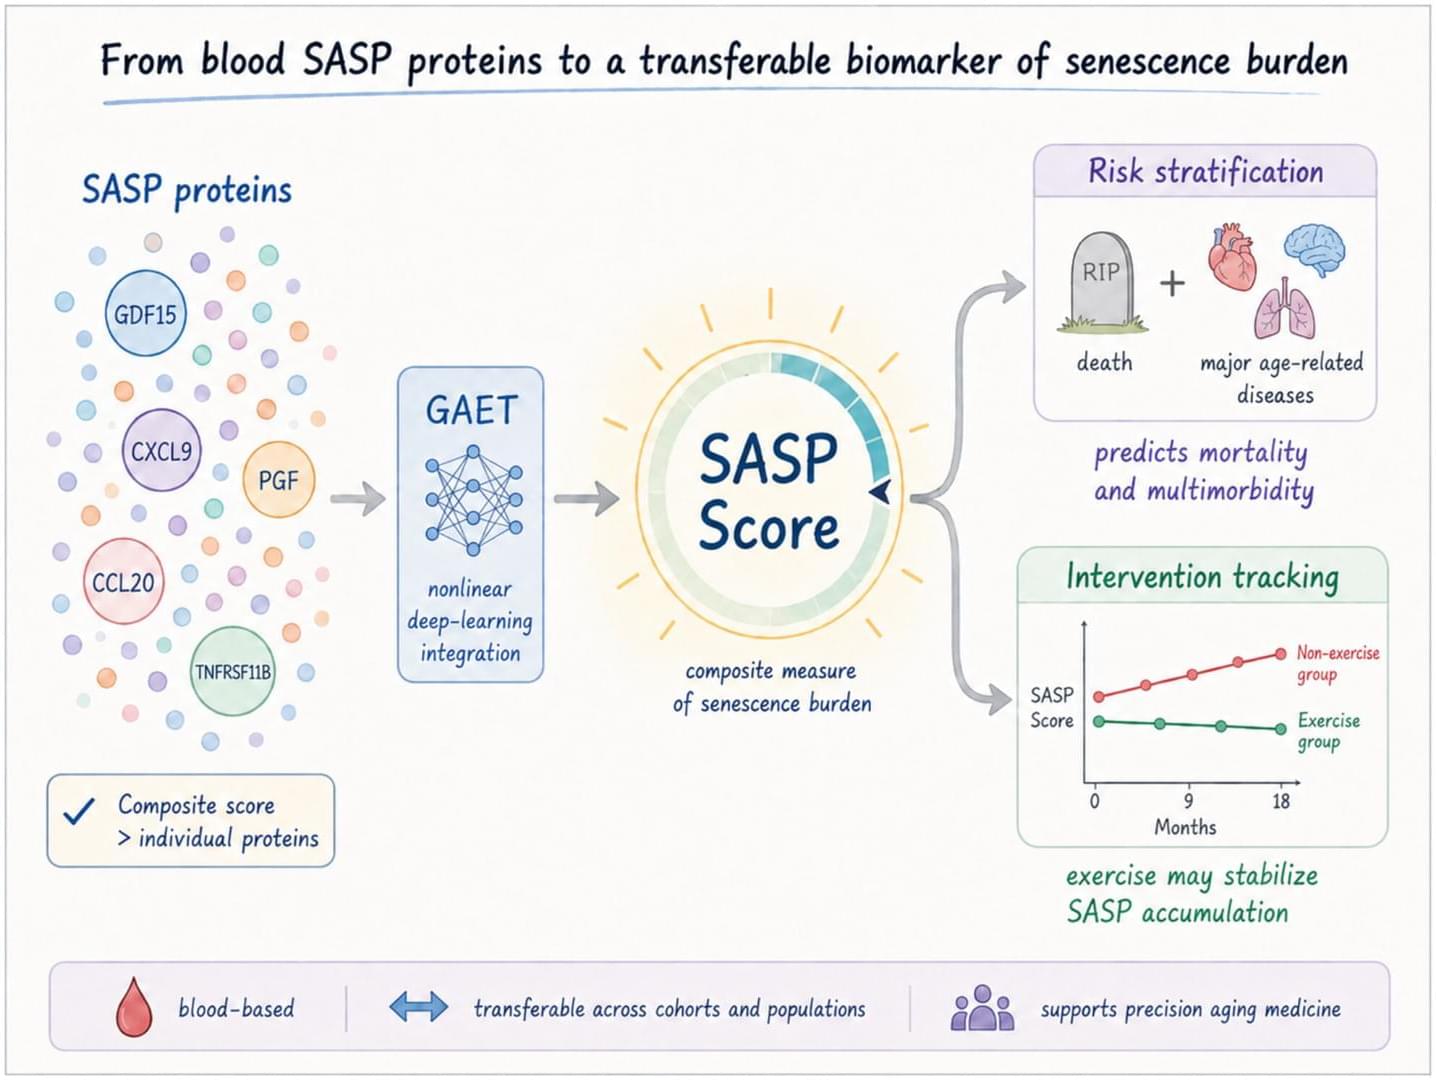
Spearman correlation coefficients were calculated between the SASP Score and chronological age, biological aging measures—including telomere length, proteomic aging clock (PAC) (Kuo et al. 2024), healthspan proteomic score (HPS) (Kuo et al. 2025), biological age (BioAge) (Sayed et al. 2021), phenotypic age (PhenoAge) (Diniz et al. 2017)—as well as other baseline aging traits including a 49-item frailty index (Williams et al. 2019) in the UK Biobank test sample. Details on the development of these biological aging measures are provided in the cited references, and the field IDs used to extract the relevant data are listed in Table S1.

The distribution of the SASP Score was compared across subgroups based on a common disease risk factor, including age group, sex, frailty status, waist-to-hip ratio group, and smoking status. Group differences were assessed using Wilcoxon rank-sum tests, with p-values adjusted for multiple testing using the Benjamini-Hochberg false discovery rate (FDR) method (Benjamini and Hochberg 1995). Additionally, the SASP Score distributions in subgroups were visualized using violin plots.

Cox proportional hazards models were used to investigate the associations of the standardized SASP Score with mortality and multiple aging-related diseases during follow-up (censored at death, or the last follow-up date of hospital inpatient data, whichever occurred first), with adjustments for baseline covariates. Mortality was ascertained through linkage to national death registries, and disease outcomes were derived using the UKB first occurrence data, which integrate multi-source data based on ICD-10 codes. Baseline covariates—including age, sex, ethnicity, education level, Townsend deprivation index (higher values associated with more material deprivation), smoking status (never, previous, current smoker), alcohol drinker status (never, previous, current drinker), systolic blood pressure, and BMI—were collected from UK Biobank online questionnaires or physical measurements at the baseline assessment. UK Biobank field IDs used to extract covariates and outcomes are provided in Table S1. Hazard ratios for each condition per SD increase in the SASP Score were reported with the multiple testing adjusted p-values using the FDR method. Model discrimination was evaluated using Harrell’s C-index, and the 95% confidence intervals were computed using a normal approximation based on the standard error of the C estimate.
/* */